You ask a chatbot for the latest FDA approval date of a drug released last week. It gives you a confident answer with a specific day and month. You check the official registry later, and the date is wrong. The model didn’t just fail; it lied with confidence. This is the core problem Generative AI faces today: the inability to recognize its own ignorance. While we obsess over making models smarter, we often ignore a more critical capability-teaching them when to stay silent. An effective abstention policy is the set of rules and mechanisms that allow an AI system to decline answering when its confidence falls below a certain threshold or when the question lies outside its training data.
Think about your last interaction with an AI assistant. Did it guess? Did it fabricate a citation? In high-stakes environments like healthcare, law, or finance, a "wrong" answer is bad, but a "confidently wrong" answer is dangerous. Abstention isn’t about laziness; it’s about safety. It’s the digital equivalent of a doctor saying, "I’m not sure, let me refer you to a specialist," instead of prescribing medication based on a hunch.
Why Confidence Is Often Misplaced
Large Language Models (LLMs) are prediction engines. They predict the next token in a sequence based on statistical probabilities learned from massive datasets. They don’t "know" facts in the way humans do; they recognize patterns. When an LLM encounters a query slightly outside its training distribution, it doesn’t hit a wall labeled "Unknown." Instead, it continues predicting the most statistically likely continuation of the text. This leads to hallucinations, where the model generates plausible-sounding but factually incorrect information.
The root cause here is poor confidence calibration. Ideally, if a model says it is 90% sure, it should be correct 90% of the time. In reality, modern LLMs are often overconfident. They might assign a high probability score to a completely made-up answer because the phrasing feels linguistically natural. Without proper calibration, the model has no internal signal to tell it, "Hey, this looks weird, maybe I shouldn’t say anything."
Defining Abstention Mechanisms
An abstention policy is not just a single switch. It’s a layered architecture involving detection, decision-making, and communication. At its core, abstention requires the model to estimate its own uncertainty. There are two main types of uncertainty the model needs to handle:
- Epistemic Uncertainty: This stems from a lack of knowledge. The model hasn’t seen enough examples of this type of question during training. For instance, asking about events after the knowledge cutoff date creates epistemic uncertainty.
- Aleatoric Uncertainty: This stems from inherent noise or ambiguity in the input. If a user asks a vague question like "What is the best stock?", there is no single correct answer. The model must recognize that the question itself is ill-posed rather than claiming ignorance of the market.
Effective policies distinguish between these. A good system will abstain on epistemic questions by saying, "My training data ends in 2023," but will attempt to clarify or provide a range for aleatoric questions.
Technical Strategies for Implementing Abstention
How do we actually make a model stop talking? Engineers use several techniques to build abstention into the inference pipeline. It’s rarely as simple as checking a confidence score, though that’s part of it.
One common approach is Self-Consistency Check. Here, the model generates multiple answers to the same prompt using different sampling temperatures. If the answers vary wildly, the variance signals low confidence. If all five generated responses contradict each other, the system triggers an abstention flag rather than picking one at random.
Another method involves Retrieval-Augmented Generation (RAG) integration. In a RAG setup, the model retrieves documents before generating an answer. An abstention policy can be tied to the retrieval step: if the retrieved chunks have a low similarity score to the query, the system knows the source material isn’t relevant. Instead of forcing the model to synthesize an answer from irrelevant text, it stops and reports that no supporting evidence was found.
More advanced labs are experimenting with verbalized uncertainty. This involves fine-tuning the model to output explicit phrases like "I am unsure" or "This may be outdated" alongside its answer. However, relying solely on verbalization is risky because models can learn to mimic uncertainty without actually having it. That’s why combining verbal cues with internal logit analysis (the raw probability scores) is more robust.
Governance and Risk Management
For enterprises deploying AI, abstention is a governance issue, not just a technical one. Your AI Governance Framework must define acceptable error rates and required behavior when confidence is low. In regulated industries, an unauthorized guess can lead to compliance violations.
Consider a legal tech company using an LLM to summarize case law. If the model hallucinates a precedent, a lawyer might waste hours chasing a non-existent ruling. The cost of abstention (the user having to search manually) is far lower than the cost of a false positive. Therefore, the policy should bias toward silence in high-risk domains.
This requires clear Service Level Agreements (SLAs) for AI performance. You need metrics beyond accuracy. You need to measure Coverage vs. Precision. Coverage is how many questions the model attempts to answer. Precision is how many of those attempts are correct. A strict abstention policy lowers coverage but raises precision. Finding the right balance depends on the business context.
Comparison of Abstention Approaches
Different strategies offer different trade-offs between computational cost, latency, and reliability. Below is a breakdown of common methods used to implement abstention policies.
| Method | Mechanism | Pros | Cons | Best For |
|---|---|---|---|---|
| Confidence Thresholding | Stop if max probability < X% | Simple, fast, low overhead | Poorly calibrated in base models | Low-latency applications |
| Self-Consistency Voting | Generate N answers; abstain if variance > Y | Robust against randomness | High compute cost (N x inference) | Complex reasoning tasks |
| RAG Relevance Score | Abstain if retrieval similarity < Z | Grounded in external data | Dependent on vector DB quality | Factual Q&A systems |
| Human-in-the-Loop | Route low-confidence queries to humans | Highest accuracy, continuous learning | Scalability limits, high labor cost | Critical decision support |
User Experience and Trust
There’s a psychological component to abstention. Users often perceive an AI that says "I don’t know" as less intelligent. We’ve conditioned people to expect search engines to always return results, even if they’re weak. Changing this expectation requires careful UX design.
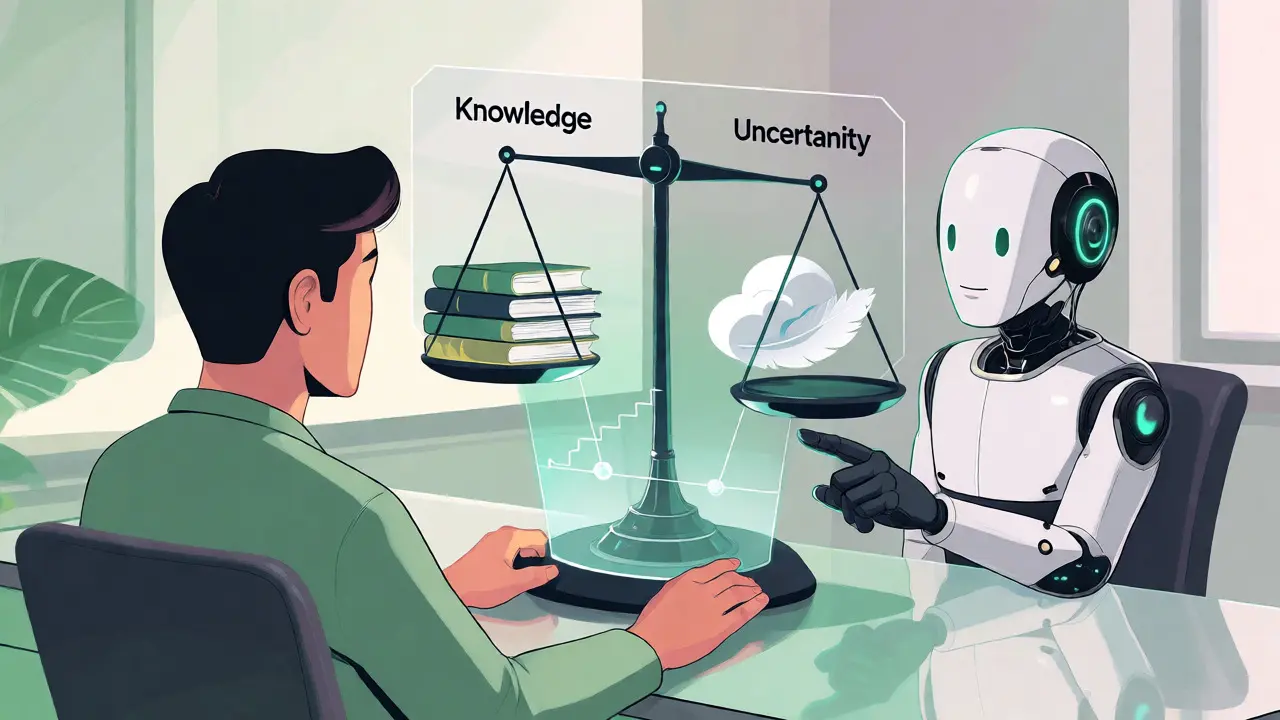
When a model abstains, the message matters. "I don’t know" is abrupt. A better response provides context: "I couldn’t find recent information on this topic in my database. Would you like me to search the web for you?" This transforms a failure state into a helpful transition. It preserves trust by showing the system understands its limitations and offers a path forward.
Furthermore, consistent abstention builds long-term credibility. If a model admits uncertainty 10% of the time but is 99% accurate on the remaining 90%, users learn to trust the affirmative answers more. Conversely, a model that never abstains but is only 85% accurate forces users to double-check every single output, reducing overall efficiency.
Evaluating Abstention Quality
How do you test if your policy works? Standard benchmarks like MMLU (Massive Multitask Language Understanding) often reward guessing. To evaluate abstention, researchers use modified metrics that penalize false positives heavily.
Key metrics include:
- Selective Accuracy: Accuracy calculated only on the subset of questions the model chose to answer.
- Abstinence Rate: The percentage of queries declined.
- Calibration Error: The difference between predicted confidence and actual accuracy.
A well-tuned system might show a slight drop in overall accuracy compared to a "guess-everything" baseline, but a massive increase in selective accuracy. For example, a model might go from 70% overall accuracy to 60% overall, but its selective accuracy on answered questions jumps from 70% to 95%. That 25-point gain in reliability is worth the 10-point loss in coverage for most professional use cases.
Future Directions and Challenges
We are moving toward models that are inherently more aware of their boundaries. Techniques like RLHF (Reinforcement Learning from Human Feedback) are being refined to reward honesty over verbosity. Future models may not just abstain but also explain why they are uncertain, distinguishing between missing data and ambiguous questions.
However, challenges remain. Over-abstention is a real risk. If a model becomes too cautious, it becomes useless. Tuning the threshold is an art form that requires constant monitoring as the model version updates or the domain shifts. Additionally, adversarial users can game abstention systems by phrasing questions to trick the confidence estimator.
Ultimately, implementing robust abstention policies is about respecting the user’s intelligence. It acknowledges that AI is a tool, not an oracle. By teaching models to say "I don’t know," we make them safer, more trustworthy, and ultimately more useful.
What is the difference between hallucination and abstention?
Hallucination occurs when a model generates false information confidently. Abstention is the mechanism that prevents this by allowing the model to decline answering when it lacks sufficient confidence or data. Hallucination is the error; abstention is the safeguard.
Does abstention reduce the usefulness of an AI model?
Not necessarily. While it reduces coverage (the number of questions answered), it significantly increases precision (the accuracy of those answers). In professional settings, users prefer fewer, highly reliable answers over many potentially wrong ones.
How do developers set the confidence threshold for abstention?
Developers analyze historical performance data to determine the optimal threshold. They plot accuracy against confidence scores to find the point where increasing the threshold yields diminishing returns on accuracy while excessively dropping coverage. This is often done via validation sets specific to the deployment domain.
Can users override an abstention decision?
Yes, many interfaces allow users to force an answer despite low confidence. This is useful for creative brainstorming where accuracy is less critical than idea generation. However, for factual queries, overriding abstention usually carries higher risk.
Are abstention policies standardized across AI providers?
No, there is no universal standard yet. Each provider implements its own proprietary methods for uncertainty estimation and abstention triggers. This makes cross-platform comparison difficult, though academic research is pushing for standardized benchmarks.