You’ve probably heard the warning before: adding more languages to your Large Language Model (LLM) training run will make it worse at everything. It’s called the "curse of multilinguality." The idea is that as you pile on data from French, Swahili, and Japanese alongside English, the model gets confused, spreading its capacity too thin and degrading performance for everyone.
But recent research says that’s mostly wrong. If you handle the data right, multilinguality isn’t a curse-it’s a superpower. The real challenge isn't just throwing more languages into the mix; it's about how you curate, balance, and filter that data before it ever hits your GPUs. This guide breaks down how to build a pretraining pipeline that actually works across dozens or hundreds of languages without tanking your benchmarks.
The Myth of Performance Degradation
For years, engineers assumed there was a zero-sum game between English and other languages. You give tokens to Spanish, you take them away from English. Simple math, right? Not quite.
Recent studies training models with 1.1B and 3B parameters on corpora spanning 25 to 400 languages proved this assumption false. When Multilingual Data is balanced correctly, combining English with non-English languages does not degrade performance for either group. In fact, it often improves generalization.
The key variable isn't the number of languages; it's Token Allocation. Every language needs enough representation in the corpus to learn its unique patterns. If you allocate too few tokens to a low-resource language like Icelandic, the model won't learn it well. But if you allocate enough, the model learns shared linguistic structures that help it understand both Icelandic and related languages better than if they were trained in isolation.
| Strategy | Token Distribution | Result on Low-Resource Languages | Result on High-Resource Languages |
|---|---|---|---|
| Naive Mixing | Equal weight per language regardless of size | Poor (undertrained) | Degraded (diluted signal) |
| Proportional Sampling | Weighted by native speaker count | Poor (still underrepresented) | Good |
| Balanced Curation | Adjusted for quality and diversity | Improved | Maintained or Improved |
Data Curation: Quality Over Quantity
Most teams start with massive web crawls like Common Crawl. For English, we have mature filtering tools. For other languages? We often just dump raw text into the model. That’s a mistake.
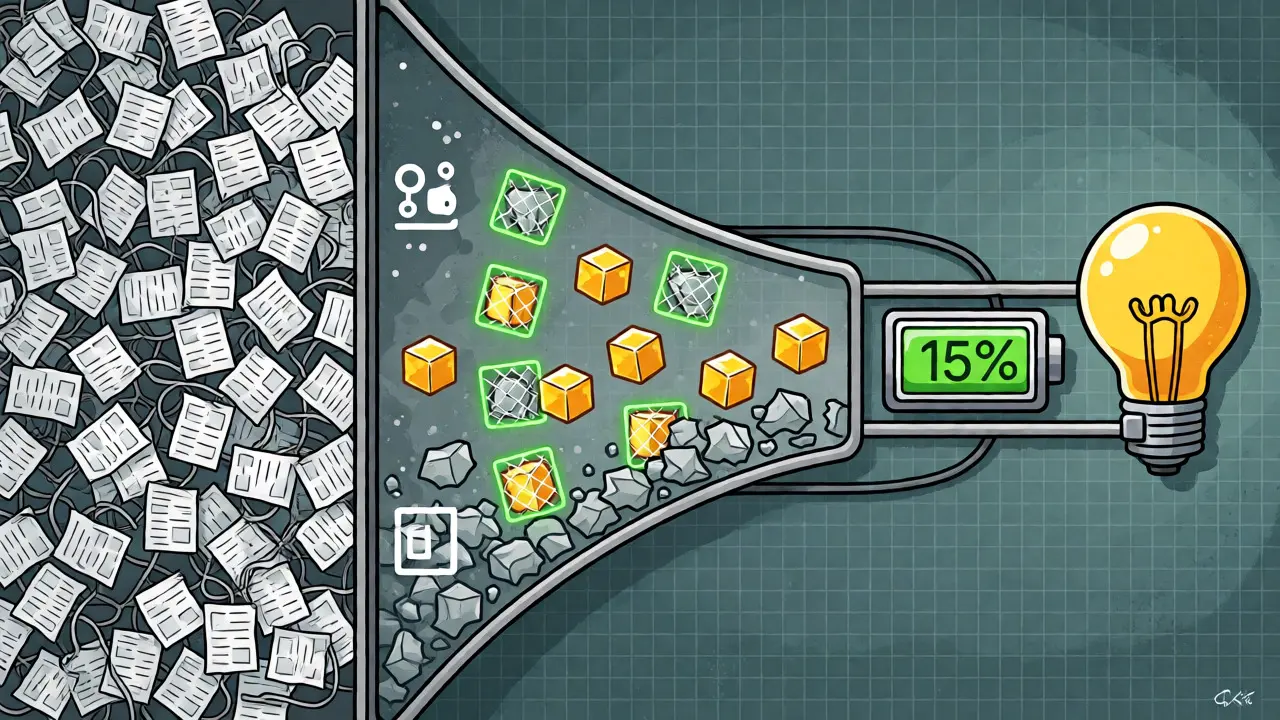
Model-Based Filtering is now essential for multilingual pipelines. Traditional rule-based filters (like checking for URL density or special characters) work okay for English but fail spectacularly for languages with different scripts or punctuation norms. Instead, use lightweight classifiers-like FastText or small Transformer models-to score each document for quality and knowledge density.
Why bother? Because you can achieve baseline performance with significantly fewer tokens. Researchers using FineWeb-2, a comprehensive web crawl dataset, found that aggressive model-based filtering allowed a 1B-parameter Llama model to hit standard MMLU scores using only 15% of the original token count. That means you save 85% of your compute budget while getting better results.
- Transparency: Use simple classifiers so you know why a document was rejected.
- Diversity: Don't just pick the top 10% of high-scoring documents; ensure you keep diverse topics and styles.
- Script Awareness: Train separate filters for Latin, Cyrillic, Arabic, and CJK scripts. One size does not fit all.
Leveraging Pivot Languages
If you’re struggling with low-resource languages, don't try to teach them directly from scratch. Use a pivot language.
A Pivot Language is a high-resource language that acts as a bridge for learning other languages. Contrary to intuition, picking a pivot language from the same family (e.g., using German to help Dutch) doesn't always yield the best results. Instead, English remains the most effective pivot language across almost all families.
Why English? It has the largest volume of structured, high-quality data. Models learn general syntactic and semantic patterns from English that transfer surprisingly well to unrelated languages. So, even if you are building a model for Thai or Zulu, keeping a significant portion of your training data in English helps the model grasp universal grammar concepts faster.
Technical Implementation Strategies
How do you actually implement this in your pipeline? There are two main paths depending on whether you are starting from scratch or extending an existing model.
Path 1: Pretraining from Scratch
This is the gold standard for maximum performance but requires massive resources. You need a tokenizer that handles all target languages efficiently. Standard byte-pair encoding (BPE) can be inefficient for non-Latin scripts, leading to inflated sequence lengths and higher costs.
- Tokenizer Training: Train a unified tokenizer on a mixed sample of all target languages. Aim for a vocabulary size that covers common words in each language without excessive fragmentation.
- Architecture: Ensure your embedding layers are large enough to support the expanded vocabulary.
- Training Loop: Mix batches carefully. Some frameworks allow sampling probabilities per language, letting you upsample rare languages during training.
Path 2: Continual Pretraining (CPT)
Most teams don't have the budget for full pretraining. They take an existing English-centric model (like Llama 3 or Mistral) and continue training it on multilingual data. This is where tools like NVIDIA NeMo come in handy. NeMo provides workflows for merging tokenizers and adjusting model architectures to accommodate new languages.
When doing CPT, watch out for catastrophic forgetting. As you train on Thai Wikipedia data, the model might forget some English nuances. To mitigate this:
- Replay Buffer: Include a small percentage (5-10%) of original English data in every batch.
- Learning Rate Schedule: Use a lower learning rate than you would for fresh pretraining to preserve existing weights.
- Layer Freezing: Consider freezing the lower layers of the transformer, which capture basic syntax, and fine-tuning the upper layers for specific language semantics.
Evaluating Multilingual Success
Don't just look at perplexity. Perplexity tells you how surprised the model is by the next word, but it doesn't tell you if the model understands meaning. You need task-specific evaluations.
Use benchmarks like XNLI (Cross-lingual Natural Language Inference) or XTREME to test reasoning across languages. Also, check for alignment issues. Does the model answer questions in the correct language? Does it refuse to answer in a language it barely knows?
A good evaluation suite should include:
- Translation Quality: BLEU or COMET scores for translation tasks.
- Question Answering: Accuracy on datasets like SQuAD translated into target languages.
- Code Generation: If your model supports code, check if it generates comments in the target language.
Common Pitfalls to Avoid
Even with the best intentions, teams make mistakes. Here are the big ones:
- Ignoring Script Normalization: Failing to normalize Unicode characters (like NFC vs NFD forms) leads to duplicate tokens and wasted capacity.
- Over-filtering: Being too aggressive with quality filters can strip out colloquial or informal speech, making the model sound robotic and unable to handle real-world user inputs.
- Static Sampling: Using fixed sampling rates throughout training. Often, it helps to start with high-resource languages to establish general capabilities, then gradually introduce low-resource languages as the model stabilizes.
Handling multilingual data isn't magic. It's engineering. It requires careful attention to token budgets, smart filtering, and realistic expectations about what a single model can do. But when done right, you get a model that doesn't just translate words-it understands cultures.
Does adding more languages always hurt model performance?
No. Recent research shows that if token allocation is sufficient for each language, adding more languages does not degrade performance. In many cases, it improves generalization through cross-lingual transfer.
What is the best pivot language for multilingual training?
English is generally the most effective pivot language due to its vast amount of high-quality, structured data. Its benefits extend across different language families, helping models learn general linguistic patterns that transfer to other languages.
How much data do I need for a low-resource language?
There is no fixed number, but quality matters more than quantity. Using model-based filtering, you can achieve good results with significantly less data. Focus on diverse, knowledge-rich samples rather than sheer volume.
Can I add a new language to an existing English-only model?
Yes, via continual pretraining. You need to expand the tokenizer to include the new language's characters and words, then continue training on a mix of the new language and original English data to prevent catastrophic forgetting.
Why is model-based filtering better than rule-based filtering for multilingual data?
Rule-based filters rely on heuristics tuned for English (like URL density or specific punctuation). These rules often fail for languages with different scripts or writing conventions. Model-based classifiers learn what "quality" looks like in each specific language context.