RIO World AI Hub

Tag: RAG latency

Latency Management for RAG Pipelines: Speed Up Production LLM Systems

Latency Management for RAG Pipelines: Speed Up Production LLM Systems

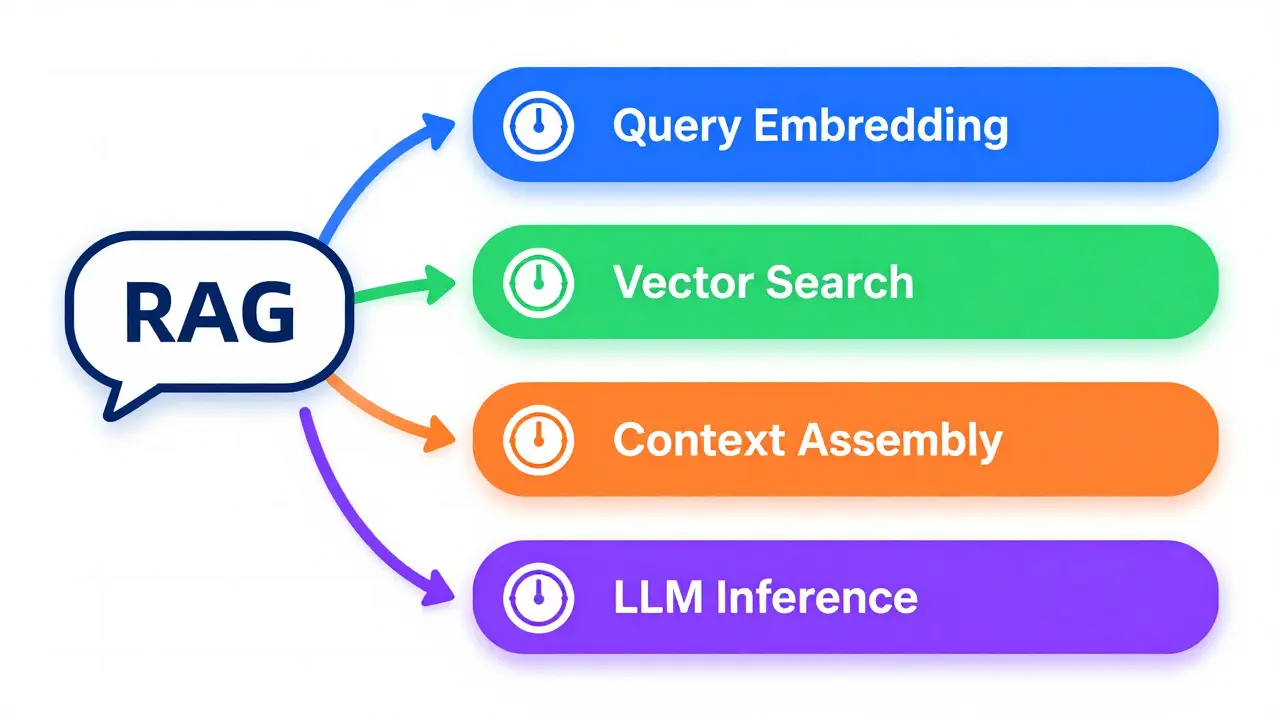
Learn how to reduce latency in production RAG pipelines. Explore Agentic RAG, vector DB optimization, and streaming techniques to achieve sub-second response times for LLM systems.

Read more

Categories

  • AI Strategy & Governance (112)
  • AI Technology (110)
  • Cybersecurity (18)

Archives

  • September 2026 (15)
  • August 2026 (30)
  • July 2026 (31)
  • June 2026 (30)
  • May 2026 (31)
  • April 2026 (26)
  • March 2026 (26)
  • February 2026 (25)
  • January 2026 (19)
  • December 2025 (5)
  • November 2025 (2)

Tag Cloud

vibe coding large language models prompt engineering AI security transformer architecture generative AI AI governance AI coding assistants AI code generation responsible AI multimodal generative AI LLM security prompt injection rapid prototyping data privacy LLM inference vibe coding security Large Language Models WCAG compliance AI development
RIO World AI Hub
Latest posts
  • Testing Strategies for Vibe-Coded Architectures: Unit, Contract, and E2E
  • Constrained Decoding for LLMs: Mastering JSON, Regex, and Schema Control
  • How to Prompt for Performance Profiling and Optimization Plans
Recent Posts
  • Scaling Multilingual LLMs: The Data Balance and Coverage Guide
  • Vibe Coding Security: What Buyers Must Assess Before Adopting AI Dev Tools
  • LLM Spend Tracking: Essential Dashboards and KPIs for Cost Control

© 2026. All rights reserved.