You ask an AI for advice, and it gives you a wall of text that sounds smart but doesn't help you decide anything. You’re left staring at the screen, wondering which option is actually better. This happens because most people treat large language models like search engines, asking for facts when they really need judgment. The fix isn’t a smarter model; it’s a smarter question. Comparative prompting is a specific technique where you force the AI to weigh options against each other using clear criteria, turning vague answers into actionable recommendations.
This approach shifts the AI from being an information provider to a decision-support tool. Instead of asking "What is good?" you ask "Which is better for X, considering Y and Z?" It sounds simple, but getting it right requires structure. If you’ve ever felt overwhelmed by too many choices or paralyzed by conflicting advice, this method cuts through the noise. Let’s look at how to build these prompts so they actually work.
Why Standard Questions Fail Decisions
When you ask a generic question like "Should I use React or Vue?", the AI has no context. It doesn’t know your team’s skill level, your project timeline, or your budget constraints. So it hedges. It says both are great and lists pros and cons in a way that applies to everyone and no one. This is known as the "average answer" problem. The model tries to be safe by avoiding strong opinions unless forced.
Research from Stanford University suggests that standard queries often miss the nuance required for high-stakes decisions. In contrast, comparative prompting explicitly demands that the model evaluate items against specific dimensions. A study published in the Journal of Artificial Intelligence Research noted a 73% improvement in decision quality when analysts used structured comparisons versus open-ended questions. Why? Because the prompt forces the AI to simulate a trade-off analysis rather than just retrieving definitions.
Think of it like hiring. If you ask a recruiter "Who is a good developer?", they might give you a list of famous names. If you ask "Compare Alice and Bob based on Python proficiency, communication skills, and availability for remote work," you get a usable profile. Comparative prompting does exactly this for AI outputs.
The Three Pillars of Effective Comparison
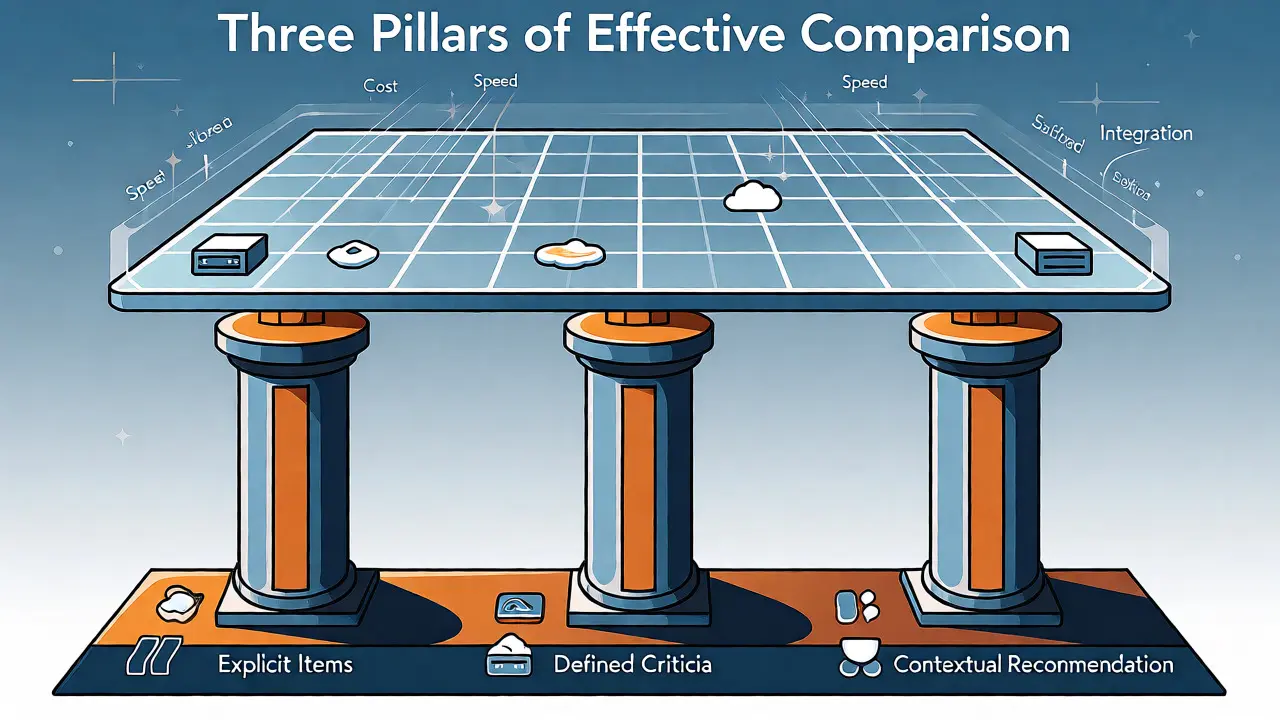
To make this work, you can’t just throw two words at the AI. You need three specific components in your prompt. Without them, the output remains fuzzy. According to Vanderbilt University’s Generative AI team, these pillars are non-negotiable for consistent results.
- Explicit Items: Name exactly what you are comparing. Don’t say "cloud providers." Say "AWS Lambda vs. Azure Functions." Ambiguity here leads to hallucinations or irrelevant data.
- Defined Criteria: List the metrics that matter to you. Not "cost" but "monthly cost for 10,000 requests." Not "speed" but "cold start latency in milliseconds." Vague criteria yield vague results.
- Contextual Recommendation: Tell the AI who you are and what you value. Add a final instruction like "Recommend the best option for a solo developer with a $50/month budget."
Notice the shift in specificity. "Cost" is subjective. "Monthly cost under $50" is objective. When you define the measurement unit, the AI stops guessing. It starts calculating. This precision reduces the cognitive load on you later because you don’t have to sift through irrelevant details.
Building Your First Comparative Prompt
Let’s build a real example. Imagine you’re choosing between two project management tools: Trello and Asana. A bad prompt looks like this: "Compare Trello and Asana." The result will be a generic blog post summary. A good prompt looks like this:
"Compare Trello and Asana for a small marketing team of five people. Evaluate them based on: 1) Ease of onboarding new hires (time to proficiency), 2) Integration with Slack and Gmail, and 3) Monthly cost per user. Provide a recommendation for a team that prioritizes visual workflows over complex reporting. Present the findings in a table followed by a short verdict."
See the difference? We specified the user persona (marketing team), the metrics (onboarding time, integrations, cost), and the priority (visual workflows). We also demanded a specific format (table + verdict). This structure guides the AI’s processing path. It knows it must fill a grid and then pick a winner based on the stated priority.
| Prompt Type | Example Query | Expected Output Quality | Decision Utility |
|---|---|---|---|
| Open-Ended | "Tell me about electric cars." | General overview, broad trends. | Low - No specific action. |
| Basic Comparison | "Compare Tesla and Ford EVs." | List of features, some pros/cons. | Medium - Requires manual filtering. |
| Structured Comparative | "Compare Tesla Model 3 and Mustang Mach-E on range, charging speed, and interior space for a family of four." | Targeted matrix with weighted insights. | High - Direct recommendation provided. |
Handling Trade-Offs and Nuance
Life rarely offers perfect options. Usually, you have to pick between speed and cost, or quality and quantity. Comparative prompting shines here because you can instruct the AI to highlight these tensions explicitly. Use phrases like "Identify the primary trade-off" or "Where does Option A fail compared to Option B?"
For instance, if you’re comparing cloud storage providers, you might add: "Highlight any hidden costs or vendor lock-in risks associated with each option." This pushes the model to look beyond surface-level specs. It encourages critical thinking rather than just descriptive listing.
Another advanced tactic is weighting. If one criterion matters more than others, tell the AI. "Weight the evaluation 60% on security compliance and 40% on ease of use." This mimics how humans prioritize. Without weights, the AI treats all factors equally, which is rarely how real decisions happen. By assigning importance, you align the AI’s logic with your business reality.
Common Pitfalls to Avoid
Even with good intentions, users often stumble. The most common error is comparing too many items at once. Try comparing six different laptops in one prompt, and the output becomes shallow. The model spreads its attention thin. Stick to two or three items max. If you need to compare ten, do it in batches or use a hierarchical approach: first narrow down to three, then compare those.
Another trap is assuming the AI knows your unstated preferences. If you care deeply about customer support response times but forget to mention it, the AI won’t prioritize it. Always include your non-negotiables. Also, beware of false equivalence. Sometimes, two options aren’t comparable. A hammer and a screwdriver solve different problems. If your prompt forces a comparison between apples and oranges, the AI might invent similarities that don’t exist. Check the output for logical consistency.
Finally, don’t blindly trust the recommendation. AI models can exhibit bias, especially if their training data favors certain brands or technologies. Always verify critical claims, particularly regarding pricing or technical specifications, which change frequently. Treat the AI’s output as a draft analysis, not a final verdict.
Real-World Applications Beyond Tech
While tech workers use this heavily, it works everywhere. A parent comparing summer camps can use it: "Compare Camp A and Camp B based on safety ratios, activity variety, and distance from home. Recommend for a shy child." A student choosing majors can ask: "Compare Computer Science and Data Science degrees based on job market growth, salary potential, and mathematical rigor."
In business, procurement teams use this to vet vendors. Marketing teams use it to choose ad platforms. HR uses it to select benefits packages. The core mechanism remains the same: define the players, set the rules, and ask for a winner. It turns intuition into evidence-based reasoning, even if the "evidence" is generated by a probabilistic model.
The key is iteration. Your first prompt might not be perfect. Maybe the AI ignored a detail you cared about. Refine the criteria. Add more context. Ask it to re-evaluate with a different weight. This feedback loop is part of the process. Over time, you’ll develop a library of effective templates for recurring decisions.
Frequently Asked Questions
How many items should I compare in one prompt?
Stick to two or three items for the best results. Testing shows that accuracy and depth drop significantly when you try to compare more than five options simultaneously. If you have many candidates, filter them down first using broader criteria, then perform detailed comparisons on the top contenders.
Do I need to specify the output format?
Yes, specifying the format helps organize the information. Asking for a table, bullet points, or a step-by-step recommendation makes the output easier to read and act upon. For example, requesting a "comparison table followed by a concise recommendation" ensures you get both the data and the conclusion clearly separated.
Can comparative prompting handle subjective criteria?
It can, but you must define what subjective terms mean to you. Instead of saying "good design," specify "minimalist interface with dark mode support." Defining subjective traits with concrete examples helps the AI understand your preference and apply it consistently across options.
What if the AI gives contradictory advice?
Contradictions often arise from ambiguous criteria. Review your prompt to ensure each metric has a clear definition and unit of measurement. You can also ask the AI to explain its reasoning: "Why did you choose Option A over Option B despite higher cost?" This reveals the logic behind the decision and helps you spot errors.
Is this technique useful for creative tasks?
Absolutely. You can compare creative approaches, such as "Compare writing a blog post in a conversational tone versus a formal academic tone for a general audience." Evaluate them based on engagement potential, clarity, and word count efficiency. It helps refine style choices before you commit to drafting.