You’ve probably heard of vibe coding-that loose, intuitive way of asking an AI to build software by just describing what you want. It’s fun for weekend hacks. But if you’ve ever watched a model hallucinate its way through a complex feature or break your entire codebase with one bad suggestion, you know it doesn’t scale. The fix isn’t better prompts; it’s better architecture. Enter context layering, a systematic approach where you feed the model structured, hierarchical information before you even ask it to write a line of code.
This method, often called context engineering, transforms AI-assisted development from a gamble into a discipline. Think of it like briefing a new junior developer. You don’t just say “build this.” You give them the project spec, the style guide, the database schema, and the specific ticket details. Context layering does exactly that for Large Language Models (LLMs). By organizing information into layers-high-level goals down to specific constraints-you reduce ambiguity and boost success rates dramatically. According to LangChain’s 2025 benchmarks, moving from pure vibe coding to proper context engineering can jump your success rate from around 35-40% to over 75%. That’s not a minor tweak; it’s the difference between a toy and a tool.
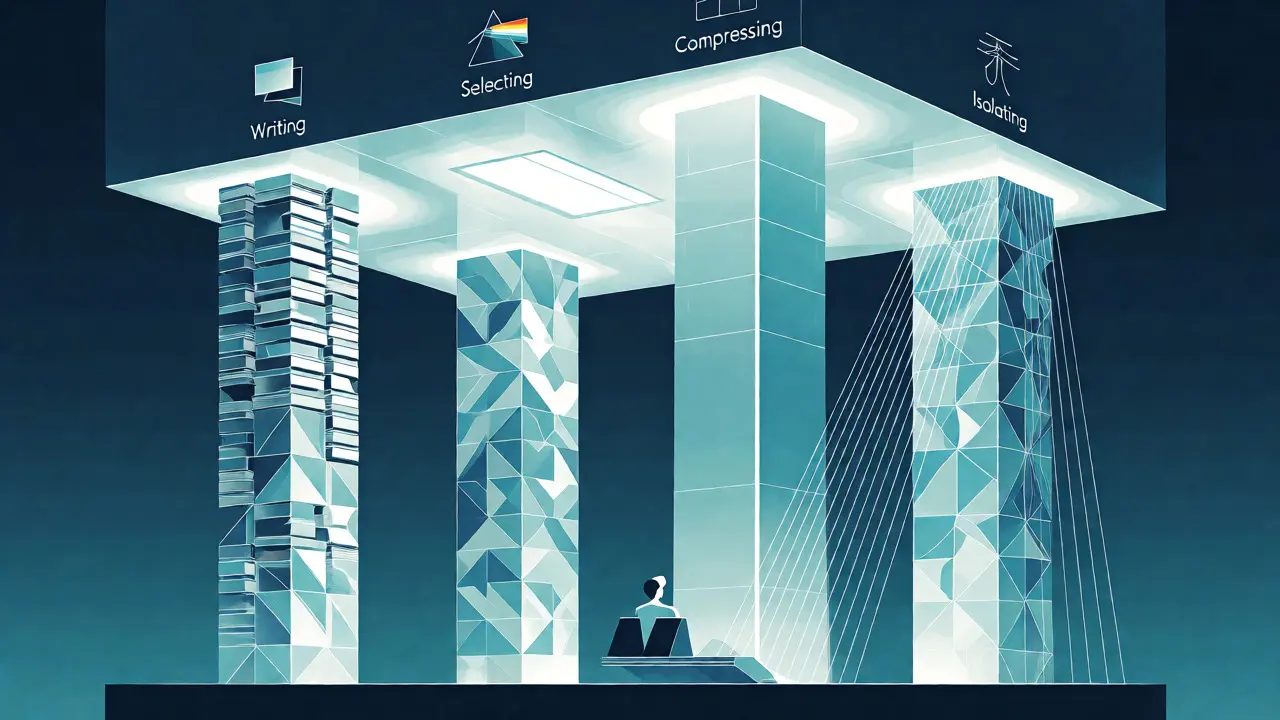
The Four Pillars of Context Engineering
To make this work, you need more than just a good memory. You need a system. Cole Medin, a key voice in this space, breaks context engineering down into four interdependent pillars. If you skip any of these, your model will likely stumble.
- Writing Context: This is about creating persistent stores of information. Instead of retyping your project rules every time, you save them. Tools like vector databases help here, allowing you to retrieve past decisions with high accuracy.
- Selecting Context: Just because you have data doesn’t mean you should send it all. You need algorithms to pull only the relevant bits for the current task. Retrieval-Augmented Generation (RAG) systems are great for this, aiming for 90%+ relevance.
- Compressing Context: LLMs have token limits. Dumping everything in causes noise. Compression techniques summarize long documents, reducing size by 40-60% while keeping the semantic meaning intact. It’s like writing an executive summary instead of sending the whole report.
- Isolating Context: This is the core of "Feed the Model Before You Ask." You break big tasks into sub-tasks and give each sub-agent only the context it needs. This prevents confusion and keeps the model focused.
Why Simple Prompting Fails at Scale
Early vibe coding worked because models were small and tasks were simple. Today’s projects are massive. When you throw a 10,000-line codebase at a model without structure, you hit three major failure modes identified by Anthropic:
- Context Overload: When the input exceeds 80% of the window capacity, the model starts forgetting earlier instructions.
- Context Confusion: Irrelevant info distracts the model. Studies show superfluous context can skew responses by up to 50%.
- Context Clash: Contradictory instructions cause failure rates to spike from 15% to 65%. If one file says "use Python" and another implies "use JavaScript," the model panics.
Context layering solves this by curating the input. For example, Anthropic’s Claude Code automatically gathers relevant info from your codebase with 92% accuracy, ensuring the model sees only what matters. This is why multi-agent systems, which isolate context for different roles, outperform single agents by 22-28% on complex tasks.
Vibe Coding vs. Context Layering: A Comparison
How do the two approaches stack up? Here’s a breakdown based on recent industry data.
| Metric | Pure Vibe Coding | Context Layering |
|---|---|---|
| Success Rate (Non-trivial tasks) | 35-40% | 75-80% |
| Hallucination Reduction | Baseline | ~60% reduction |
| Upfront Time Investment | Low | 30-40% higher |
| Suitability for Large Projects | Fails beyond ~500 lines | Maintains 70%+ success at 10k+ lines |
The trade-off is clear: context layering takes more time upfront. You spend weeks setting up your context stores and retrieval logic. But for production apps, especially in compliance-heavy sectors like finance, this investment pays off. JPMorgan noted a 3.2x adoption rate for context layering in financial services due to reduced regulatory errors.
How to Implement Context Layering Step-by-Step
You don’t need to rebuild your entire workflow overnight. Start small. Most developers take 2-3 weeks to get comfortable. Here’s a practical path:
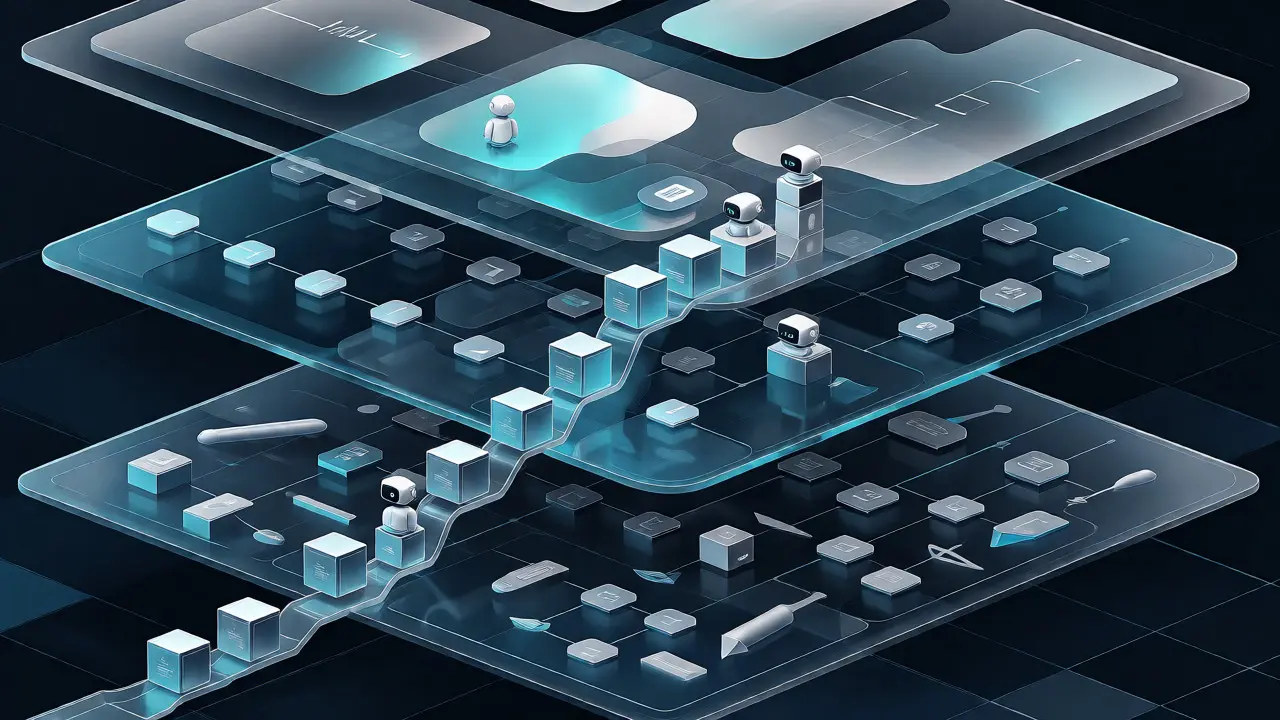
- Define Your Layers: Create a hierarchy. Level 1: Project Goals. Level 2: Tech Stack & Rules. Level 3: Specific Module Details. Level 4: Current Task Constraints.
- Set Up Persistent Storage: Use a vector database like Pinecone. Aim for a cosine similarity threshold above 0.85 to ensure retrieved context is actually relevant.
- Implement Selection Logic: Don’t dump everything. Write a script that pulls only the top-k most relevant chunks for the current prompt. RAG systems handle this well.
- Compress Long Docs: Summarize lengthy API docs or legacy code comments. Preserve the core logic but cut the fluff. Semantic summarization tools can keep 90% of value while cutting tokens in half.
- Test with Isolation: Try breaking a big request into three smaller ones, each with its own isolated context. Compare the output quality against a single monolithic prompt.
One developer reported reducing bug rates by over 50% just by isolating context for specific subtasks. Another case study showed error rates dropping from 37% to 9% in an e-commerce app after implementing layered delivery.
Common Pitfalls to Avoid
Even with the best intentions, you can mess this up. Watch out for these traps:
- Overloading the Window: More context isn’t always better. Keep it lean. If you’re near the limit, compress or prune.
- Fragmented Memory: If your context jumps around too much, the model loses track of the overall goal. Use "memory zero" techniques to maintain consistent personality and traits across layers.
- Ignoring Freshness: Old context can conflict with new changes. Regularly update your persistent stores to reflect the latest code state.
Remember, context engineering isn’t just a hack. Sequoia Capital calls it the "necessary infrastructure layer" for serious LLM applications. As Gartner predicts, 70% of enterprise AI coding will use formal context practices by 2027. Getting ahead of this curve now means you’re building robust systems, not just playing with toys.
What is the main difference between vibe coding and context layering?
Vibe coding relies on natural language prompts and intuition, often leading to inconsistent results. Context layering involves structuring and feeding specific, hierarchical information to the model before the request, turning AI coding into a reliable engineering process with higher success rates.
Does context layering require expensive tools?
Not necessarily. While advanced setups might use vector databases like Pinecone or frameworks like LangChain, you can start with simple text files and manual selection. The methodology is more about organization than specific expensive tech.
How much time does it take to learn context layering?
Most developers report spending 2-3 weeks mastering the fundamentals. This includes learning how to structure context, set up retrieval systems, and practice compression techniques. The initial setup requires 30-40% more design time than basic prompting.
Can context layering help with large codebases?
Yes, it excels here. Pure vibe coding often fails in projects over 500 lines. Context layering maintains high success rates (70%+) even in projects with 10,000+ lines by isolating relevant parts and preventing context overload.
What are the risks of poor context management?
Poor management leads to context overload, confusion, or clash. This can cause failure rates to jump from 15% to 65%. Superfluous context can also skew responses by up to 50%, making the model less accurate despite having more information.