You ask a large language model a tricky math problem or a complex logical puzzle. It spits out an answer instantly. Is it right? Maybe. But did it actually think about it, or just pattern-match the most likely next word? This is the core challenge of modern AI. We’ve moved past simple text generation into an era where we demand that models reason. To get there, engineers rely on three specific techniques: Chain-of-Thought, a prompting technique that encourages models to generate intermediate reasoning steps before delivering a final answer, Self-Consistency, a method that generates multiple reasoning paths and selects the most frequent answer to improve reliability, and Debate, a framework where multiple models or reasoning paths challenge each other to reach a more robust conclusion. These aren't just academic buzzwords; they are the engines driving the latest leaps in AI capability.
Why Simple Prompting Isn't Enough
Standard prompting treats an LLM like a very sophisticated autocomplete engine. You give it a start, it predicts the end. For simple facts, this works great. Ask "What is the capital of France?" and you get Paris. No thinking required. But ask "If I have 5 apples, eat 2, buy 3 more, and then split them equally with a friend, how many do I have?" and a basic model might stumble. It tries to jump straight to the number without doing the math steps. This is where reasoning methods come in. They force the model to slow down and show its work.
The goal isn't just accuracy; it's interpretability and trust. When a model outputs a long chain of logic, you can see where it went wrong if the answer is incorrect. This transparency is critical for high-stakes fields like healthcare and law. Recent data from Microsoft Research shows that using these reasoning strategies can boost performance on complex tasks by up to 35% compared to standard prompting, even on smaller models. That’s a massive gain for such a low-cost intervention.
Chain-of-Thought: Showing Your Work
Chain-of-Thought (CoT) was introduced by Google Research in early 2022. The idea is simple: instead of asking for the answer directly, you prompt the model to explain its reasoning step-by-step. Think of it as telling a student, "Don't just write the answer; show your calculations."
When you use CoT, the model generates a sequence of intermediate thoughts. For example, in a math problem, it might first calculate the total apples, then subtract the eaten ones, add the new ones, and finally divide. MIT research from late 2024 found that optimal performance often occurs when models generate between 3 and 7 distinct reasoning steps. Too few, and you miss the logic; too many, and the model might hallucinate unnecessary complexity.
One key advantage of CoT is its efficiency. It doesn't require retraining the model. You just change the prompt. However, it’s not magic. If the model lacks the underlying knowledge, showing steps won’t fix the gaps. It helps organize what the model knows, but it can’t teach it new facts. Developers often use "Wait" tokens or explicit instructions like "Let's think step by step" to trigger this behavior. It’s the entry-level tool for anyone wanting to upgrade their AI’s brainpower.
Self-Consistency: Voting for the Best Answer
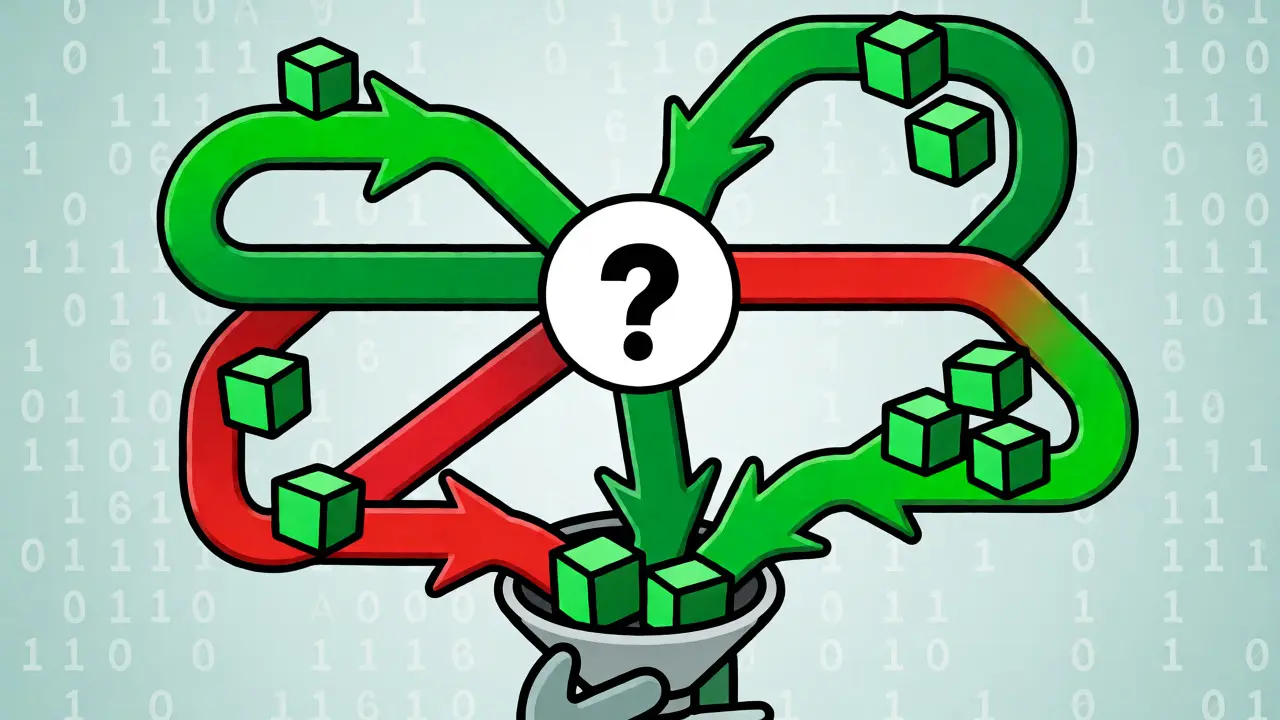
If Chain-of-Thought is about one careful path, Self-Consistency is about taking multiple paths and seeing where they converge. Introduced shortly after CoT, this method acknowledges that LLMs are probabilistic. Sometimes, the first reasoning path has a glitch. So, why not try again?
In practice, Self-Consistency involves generating several different reasoning chains for the same question-typically 5 to 10 diverse paths. Then, the system looks at the final answers produced by each chain. The answer that appears most frequently is selected as the correct one. It’s like holding a vote among ten experts who all solved the problem independently. If eight say "42" and two say "43," you go with 42.
This approach significantly reduces random errors. A single bad reasoning step can derail a CoT response, but Self-Consistency filters out those outliers. The trade-off is speed and cost. Since you’re running the model multiple times, latency increases. One developer noted that API calls took 3.2x longer when using five reasoning paths. For real-time chatbots, this might be too slow. But for batch processing, scientific analysis, or coding tasks where accuracy trumps speed, it’s invaluable.
AI Debate: Stress-Testing Logic
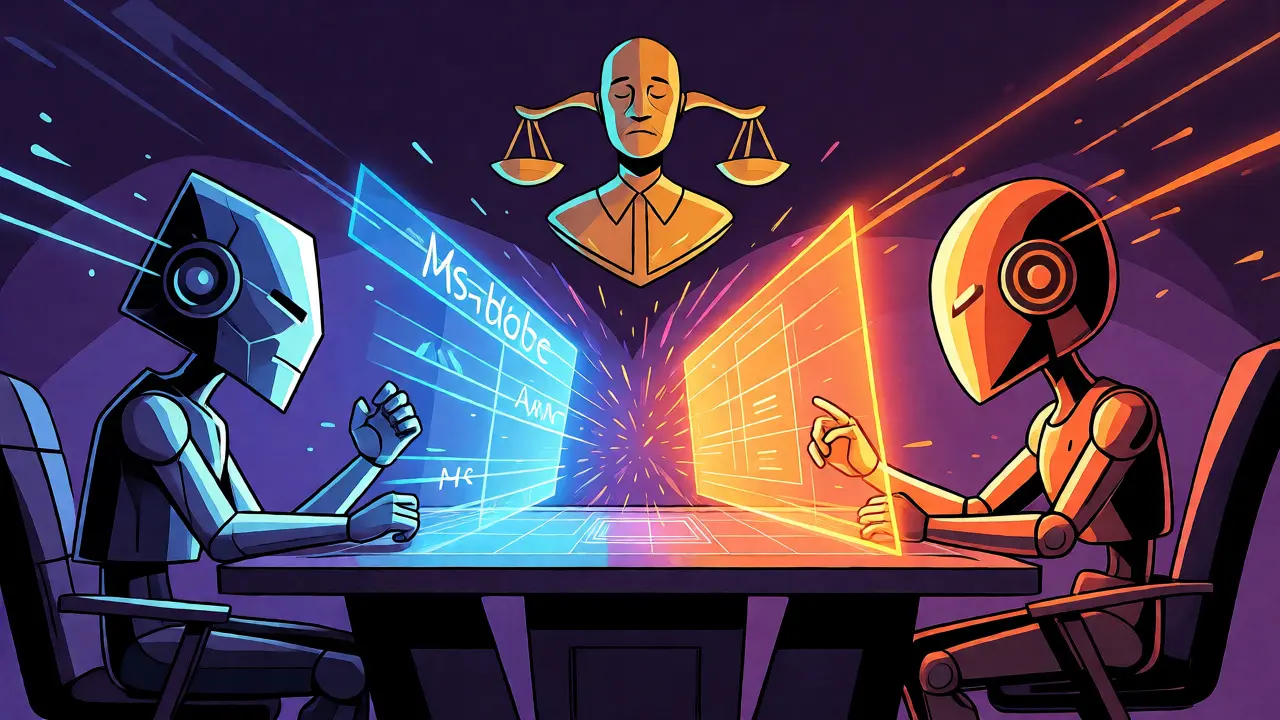
Sometimes, you don’t just want the most common answer; you want the most defensible one. Enter AI Debate. Formalized by researchers at Anthropic and others, this method pits multiple models or reasoning agents against each other. Imagine two lawyers arguing a case before a judge. Each side presents arguments, attacks the other’s weaknesses, and refines their position. Finally, a neutral evaluator decides who made the stronger case.
Debate frameworks typically employ 3 to 5 specialized models. They generate contrasting viewpoints. One model might argue for Solution A, while another defends Solution B. They exchange critiques, highlighting flaws in each other’s logic. This adversarial process exposes subtle errors that a single reasoning path might miss. It’s particularly effective for subjective or complex problems where there isn’t one obvious "right" answer, such as ethical dilemmas or strategic planning.
The catch? Complexity. Setting up a debate system requires more infrastructure than simple prompting. You need a meta-evaluator to judge the outcomes, which adds another layer of potential error. However, for high-value decisions, the extra rigor pays off. Studies suggest that debate can uncover biases and improve the robustness of conclusions, making it a favorite for safety-critical applications.
Comparing the Three Approaches
Choosing the right method depends on your resources and goals. Here’s a quick breakdown of how they stack up against each other:
| Feature | Chain-of-Thought | Self-Consistency | AI Debate |
|---|---|---|---|
| Primary Mechanism | Single sequential reasoning path | Multiple independent paths + voting | Adversarial argumentation + evaluation |
| Computational Cost | Low (1x inference) | Medium-High (5-10x inference) | High (3-5x inference + eval) |
| Best Use Case | General logic, math, coding | High-accuracy needs, noisy data | Complex decision-making, safety checks |
| Latency Impact | Negligible | Significant (3x+ slower) | Very High |
| Error Reduction | Moderate | High | Very High (for robustness) |
Notice the clear trade-offs. CoT is cheap and fast but less reliable for hard problems. Self-Consistency buys accuracy with time. Debate buys robustness with complexity. Most advanced systems today blend these. For instance, you might use CoT to generate initial ideas, then apply Self-Consistency to filter them, and finally run a mini-debate on the top candidates.
Real-World Performance and Pitfalls
It’s tempting to think these methods are silver bullets. They aren’t. Apple’s machine learning team identified a troubling phenomenon called "reasoning collapse." Beyond a certain complexity threshold, adding more reasoning steps actually hurts performance. The model gets lost in its own logic, spiraling into contradictions. This suggests that current architectures still lack true human-like cognitive limits management.
Another issue is the "illusion of thinking." Users report that models generate beautiful, coherent-sounding chains that contain subtle logical errors. In one study, 38% of complex cases contained hidden flaws despite looking convincing. This highlights the danger of over-trusting AI output. Just because it explains itself clearly doesn’t mean it’s right.
However, the gains are real. Distillation techniques, like those used in DeepSeek-R1, allow smaller models to inherit reasoning capabilities from larger ones. Qwen and Llama models fine-tuned with this data showed 28% higher accuracy on logical deduction tasks. This means you don’t always need a massive server farm to get smart results. Strategic prompting and training data matter more than raw size alone.
Implementation Tips for Developers
If you’re building with LLMs, start small. Don’t jump straight into Debate. Begin with Chain-of-Thought prompts. Add "Let's think step by step" to your system instructions and measure the impact. If accuracy improves but variance remains high, introduce Self-Consistency. Generate 5 paths and pick the majority vote.
Watch your token budgets. Reasoning consumes tokens rapidly. MIT’s adaptive reasoning research suggests dynamically adjusting computational effort based on problem difficulty. Easy questions should get short answers; hard ones deserve deep dives. Implementing this logic requires a separate scoring model, known as a Process Reward Model (PRM), which can take days to train properly.
Finally, monitor for instability. Advanced reasoning can sometimes make things worse. If your customer service bot starts giving weirdly philosophical answers to simple pricing questions, you’ve over-engineered the solution. Keep reasoning depth proportional to task complexity.
Frequently Asked Questions
Does Chain-of-Thought require model retraining?
No, Chain-of-Thought is primarily a prompting technique. You modify the input prompt to encourage step-by-step reasoning. However, some advanced variants involve fine-tuning the model on datasets containing reasoning traces, which does require training.
How much slower is Self-Consistency compared to standard prompting?
Self-Consistency typically increases latency by 3x to 5x, depending on how many reasoning paths you generate. If you generate 5 paths, the model runs 5 times. This makes it suitable for background tasks but potentially problematic for real-time chat interfaces.
Can AI Debate eliminate hallucinations completely?
No method eliminates hallucinations completely. AI Debate significantly reduces them by exposing logical inconsistencies through adversarial critique. However, if the base models share the same factual biases, the debate may reinforce rather than correct those errors.
Which reasoning method is best for mathematics?
Chain-of-Thought combined with Self-Consistency is generally the most effective for mathematics. CoT ensures the calculation steps are visible, while Self-Consistency filters out arithmetic errors by selecting the most frequent correct result across multiple attempts.
Do smaller models benefit from these reasoning techniques?
Yes, but with caveats. Smaller models (under 7 billion parameters) can struggle with the context length required for long reasoning chains. However, distillation techniques allow small models to learn reasoning patterns from larger ones, yielding significant accuracy improvements without the massive compute cost.