Tag: Chain-of-Thought
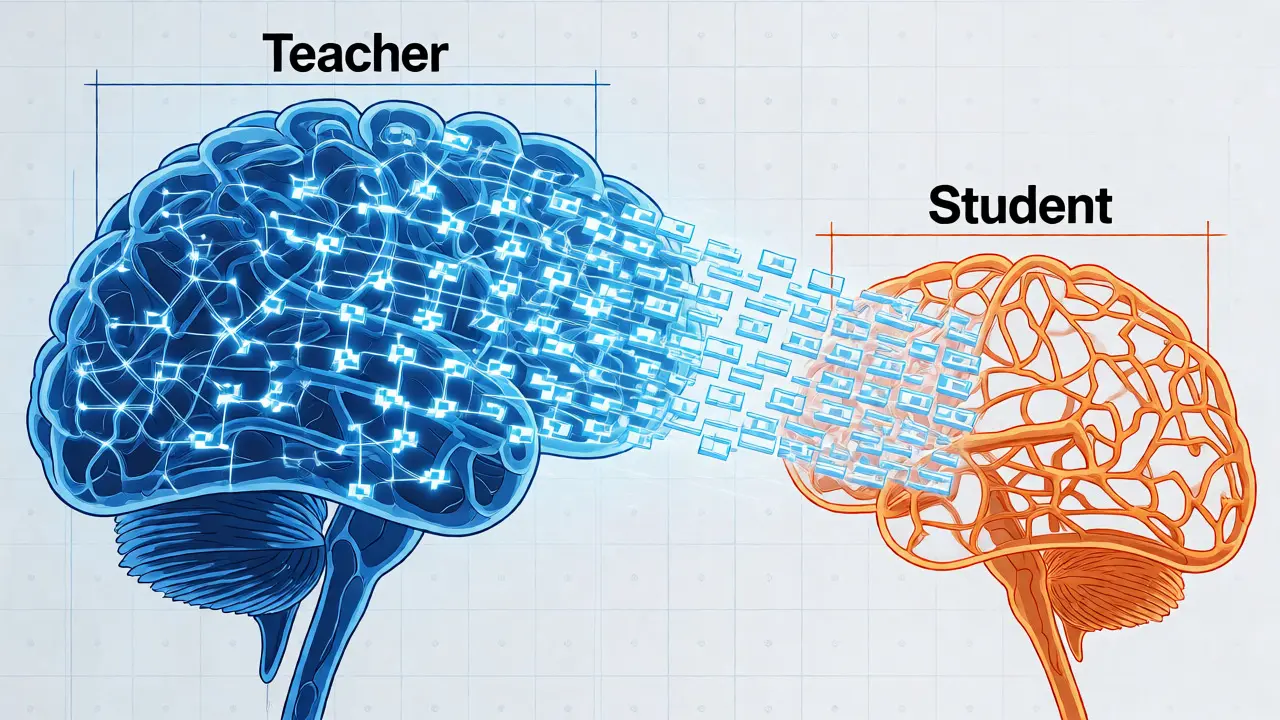
Distilling Reasoning: How Small LLMs Learn Chain-of-Thought
Discover how smaller language models learn to reason via Chain-of-Thought distillation. We compare pre-thinking vs. post-thinking methods, analyze performance gaps, and offer practical tips for implementation.
Read more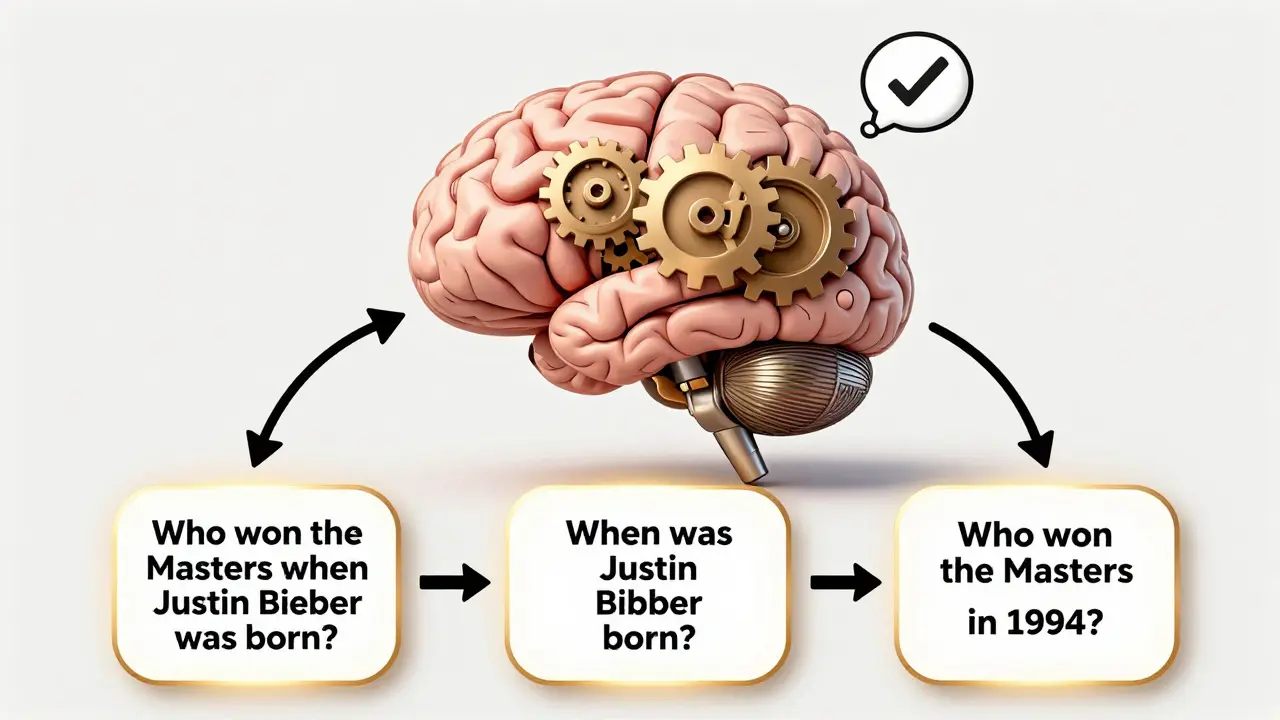
Self-Ask and Decomposition Prompts for Complex LLM Questions
Self-Ask and Decomposition Prompts improve LLM accuracy on complex questions by breaking them into clear, verifiable steps. Used in legal, medical, and financial AI systems, they boost reasoning accuracy by over 13%-but come with higher costs and latency.
Read more