RIO World AI Hub

Tag: large language model testing
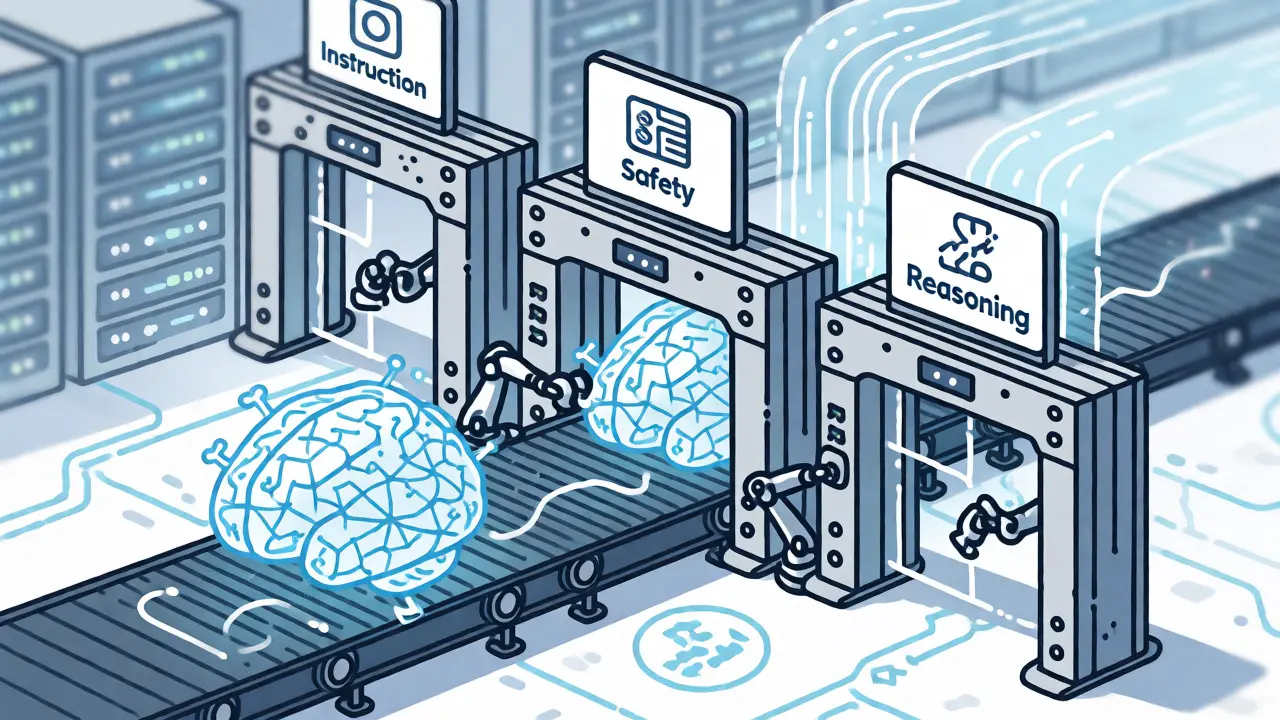
Post-Training Evaluation Gates: Shipping LLMs Safely

Post-Training Evaluation Gates: Shipping LLMs Safely

Learn how post-training evaluation gates prevent LLM failures in production. Discover best practices for SFT validation, safety checks, and human review.

Read more

Categories

  • AI Technology (138)
  • AI Strategy & Governance (126)
  • Cybersecurity (22)

Archives

  • October 2026 (31)
  • September 2026 (30)
  • August 2026 (30)
  • July 2026 (31)
  • June 2026 (30)
  • May 2026 (31)
  • April 2026 (26)
  • March 2026 (26)
  • February 2026 (25)
  • January 2026 (19)
  • December 2025 (5)
  • November 2025 (2)

Tag Cloud

vibe coding large language models prompt engineering AI governance generative AI LLM security prompt injection AI security transformer architecture data privacy rapid prototyping AI coding assistants AI code generation responsible AI multimodal generative AI AI development LLM inference vibe coding security LLM hallucinations LoRA
RIO World AI Hub
Latest posts
  • Data Privacy in Prompts: How to Redact Secrets and Regulated Information Before Using AI
  • Cybersecurity and Generative AI: Threat Reports, Playbooks, and Simulations for 2026
  • Structured vs Unstructured Pruning: Making LLMs Efficient
Recent Posts
  • Secure Branch Protection for Vibe-Coded Repositories: A Practical Guide
  • Testing and Monitoring RAG Pipelines: Synthetic Queries vs. Real Traffic
  • Distilling Reasoning: How Small LLMs Learn Chain-of-Thought

© 2026. All rights reserved.