RIO World AI Hub

Tag: streaming responses
Latency Optimization for Large Language Models: Streaming, Batching, and Caching

Latency Optimization for Large Language Models: Streaming, Batching, and Caching

Learn how to reduce LLM response times using streaming, dynamic batching, and KV caching. Discover practical strategies to cut latency by up to 97% and boost user engagement without sacrificing output quality.

Read more
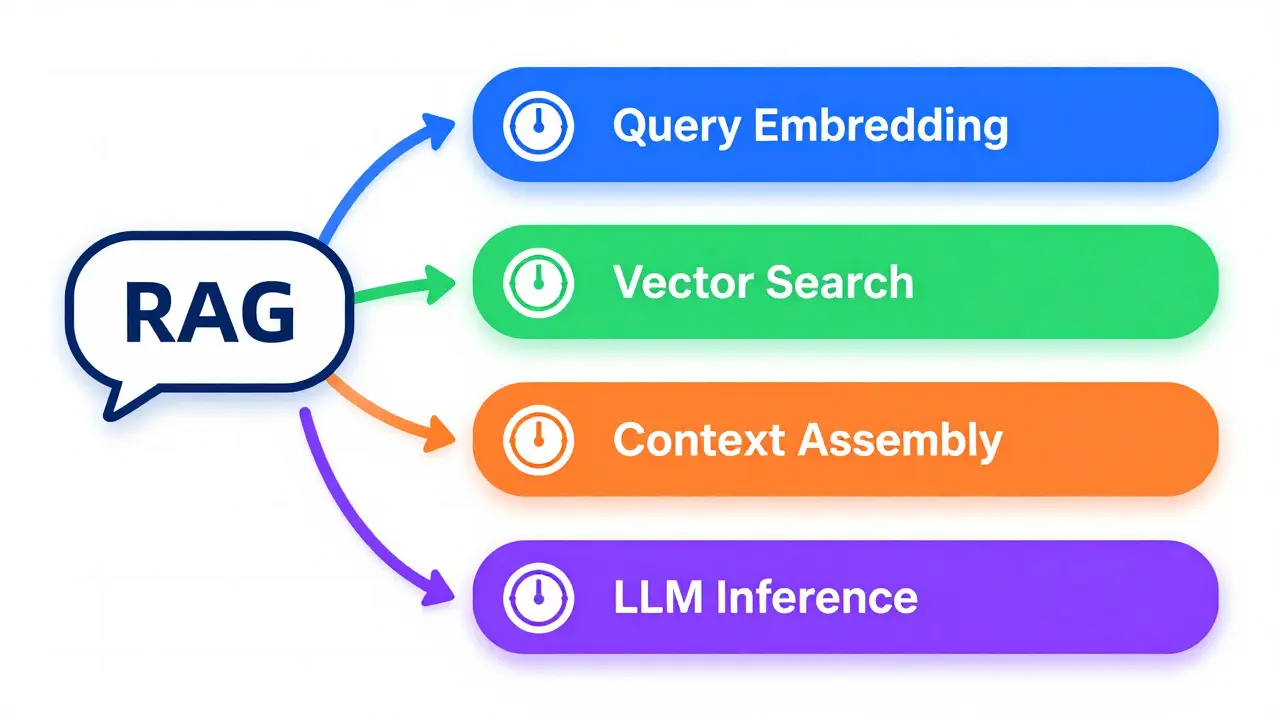
Latency Management for RAG Pipelines: Speed Up Production LLM Systems

Latency Management for RAG Pipelines: Speed Up Production LLM Systems

Learn how to reduce latency in production RAG pipelines. Explore Agentic RAG, vector DB optimization, and streaming techniques to achieve sub-second response times for LLM systems.

Read more

Categories

  • AI Technology (149)
  • AI Strategy & Governance (128)
  • Cybersecurity (23)

Archives

  • November 2026 (14)
  • October 2026 (31)
  • September 2026 (30)
  • August 2026 (30)
  • July 2026 (31)
  • June 2026 (30)
  • May 2026 (31)
  • April 2026 (26)
  • March 2026 (26)
  • February 2026 (25)
  • January 2026 (19)
  • December 2025 (5)

Tag Cloud

vibe coding large language models prompt engineering generative AI AI governance LLM security prompt injection AI security transformer architecture data privacy rapid prototyping AI coding assistants AI code generation responsible AI multimodal generative AI AI development LLM inference Large Language Models AI-assisted development vibe coding security
RIO World AI Hub
Latest posts
  • Token Budgets and Quotas: How to Stop LLM Cost Overruns
  • Instruction Tuning for LLMs: How to Build Better AI Followers
  • AI Code Regulation Outlook 2026: EU AI Act, US Laws & Compliance
Recent Posts
  • Choosing Embedding Dimensionality for RAG Systems: A Practical Guide
  • Developer Sentiment Surveys on Vibe Coding: What to Ask and Why
  • Training Data Pipelines for Generative AI: Deduplication, Filtering, and Mixture Design

© 2026. All rights reserved.