RIO World AI Hub

Tag: OpenTelemetry monitoring
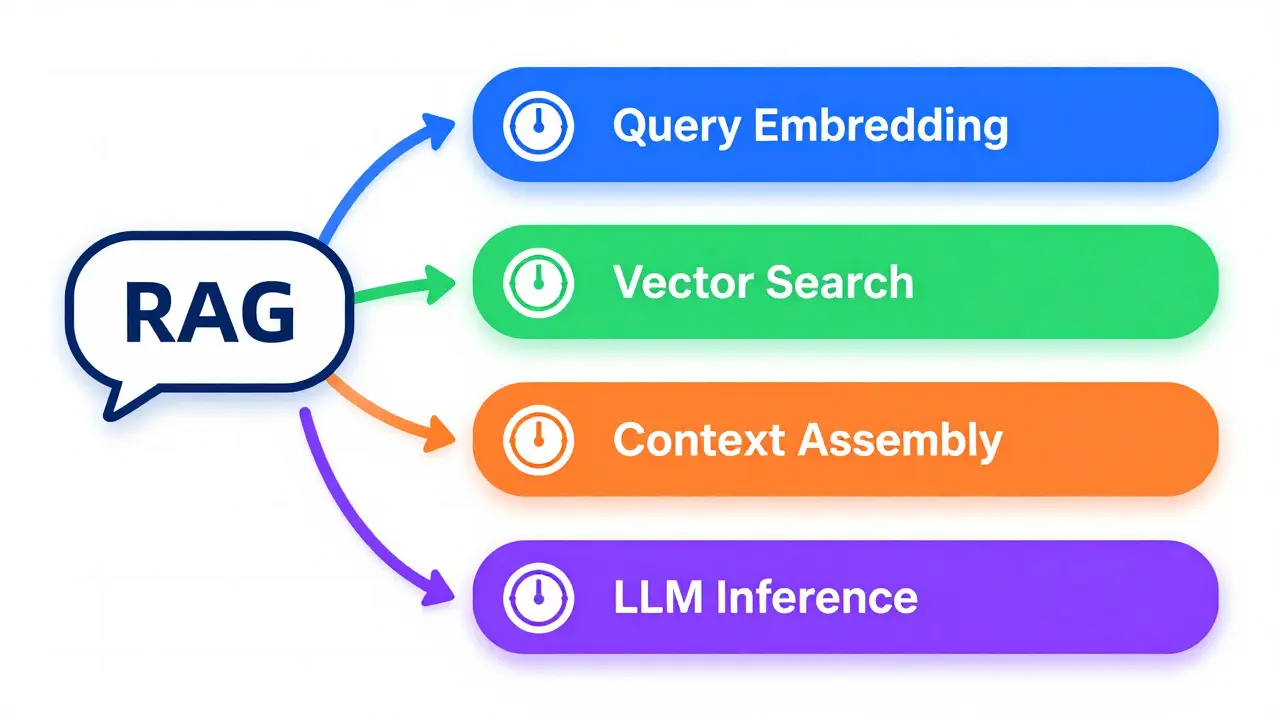
Latency Management for RAG Pipelines: Speed Up Production LLM Systems

Latency Management for RAG Pipelines: Speed Up Production LLM Systems

Learn how to reduce latency in production RAG pipelines. Explore Agentic RAG, vector DB optimization, and streaming techniques to achieve sub-second response times for LLM systems.

Read more

Categories

  • AI Technology (135)
  • AI Strategy & Governance (123)
  • Cybersecurity (22)

Archives

  • October 2026 (25)
  • September 2026 (30)
  • August 2026 (30)
  • July 2026 (31)
  • June 2026 (30)
  • May 2026 (31)
  • April 2026 (26)
  • March 2026 (26)
  • February 2026 (25)
  • January 2026 (19)
  • December 2025 (5)
  • November 2025 (2)

Tag Cloud

vibe coding large language models prompt engineering generative AI AI governance LLM security AI security transformer architecture data privacy prompt injection rapid prototyping AI coding assistants AI code generation responsible AI multimodal generative AI AI development LLM inference vibe coding security LLM hallucinations LoRA
RIO World AI Hub
Latest posts
  • Stop Vibe Coding: Anti-Pattern Prompts That Break LLM Security
  • Firebase Studio and Vibe Coding: Auto-Provisioned Backends in Minutes
  • Levels of Autonomy in LLM Agents: From L1 to L4 Explained
Recent Posts
  • Context Layering for Vibe Coding: How to Feed the Model Before You Ask
  • Toolformer-Style Self-Supervision: How LLMs Learn to Use Tools
  • Model Lifecycle Management: Navigating LLM Updates and Deprecations

© 2026. All rights reserved.