RIO World AI Hub

Tag: small language models
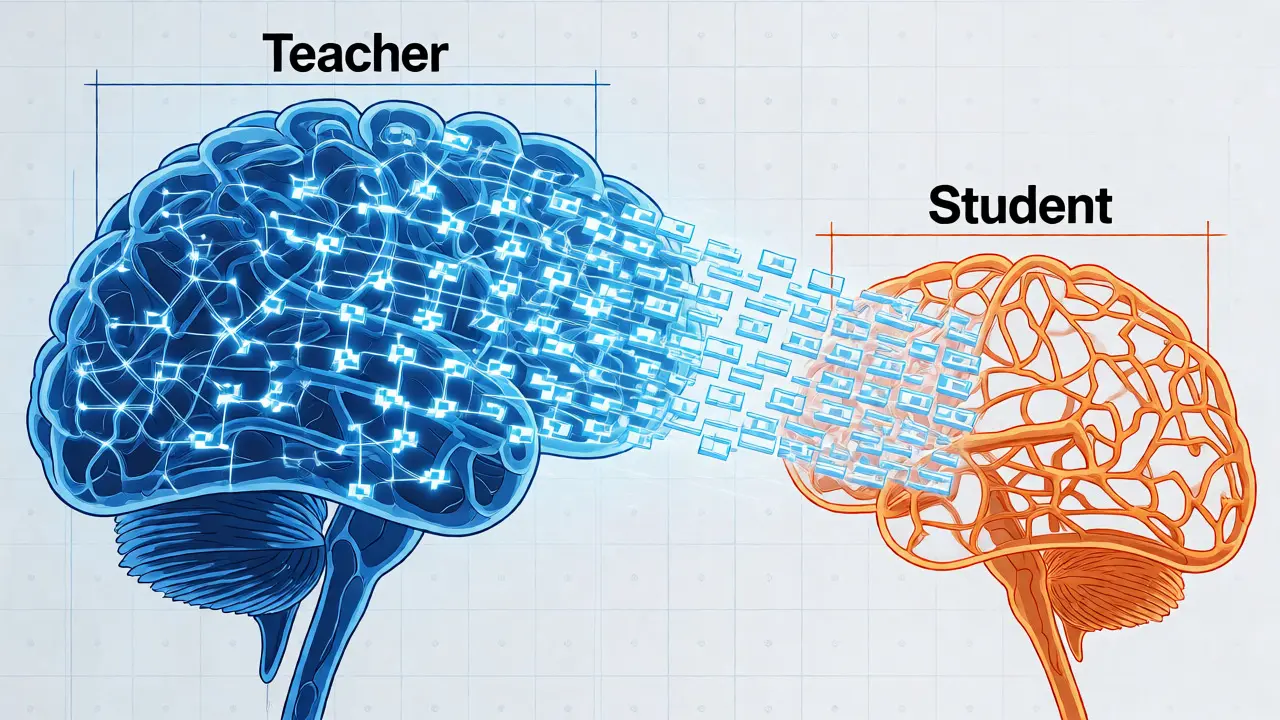
Distilling Reasoning: How Small LLMs Learn Chain-of-Thought

Distilling Reasoning: How Small LLMs Learn Chain-of-Thought

Discover how smaller language models learn to reason via Chain-of-Thought distillation. We compare pre-thinking vs. post-thinking methods, analyze performance gaps, and offer practical tips for implementation.

Read more

Categories

  • AI Technology (154)
  • AI Strategy & Governance (129)
  • Cybersecurity (23)

Archives

  • November 2026 (20)
  • October 2026 (31)
  • September 2026 (30)
  • August 2026 (30)
  • July 2026 (31)
  • June 2026 (30)
  • May 2026 (31)
  • April 2026 (26)
  • March 2026 (26)
  • February 2026 (25)
  • January 2026 (19)
  • December 2025 (5)

Tag Cloud

vibe coding large language models prompt engineering generative AI AI governance LLM security prompt injection AI security transformer architecture data privacy rapid prototyping AI coding assistants AI code generation responsible AI multimodal generative AI AI development LLM inference Large Language Models Transformer architecture AI-assisted development
RIO World AI Hub
Latest posts
  • Procurement Checklists for Vibe Coding Tools: Security and Legal Terms
  • GPU Selection for LLM Inference: A100 vs H100 vs CPU Offloading
  • Hardware Trends That Accelerate Vibe Coding: GPUs, NPUs, and Edge
Recent Posts
  • Transformer Architecture in Generative AI: A Practical Guide for Engineers
  • Rotary Position Embeddings (RoPE): The Engine Behind Long-Context LLMs
  • Reasoning in Large Language Models: Chain-of-Thought, Self-Consistency, and Debate Explained

© 2026. All rights reserved.