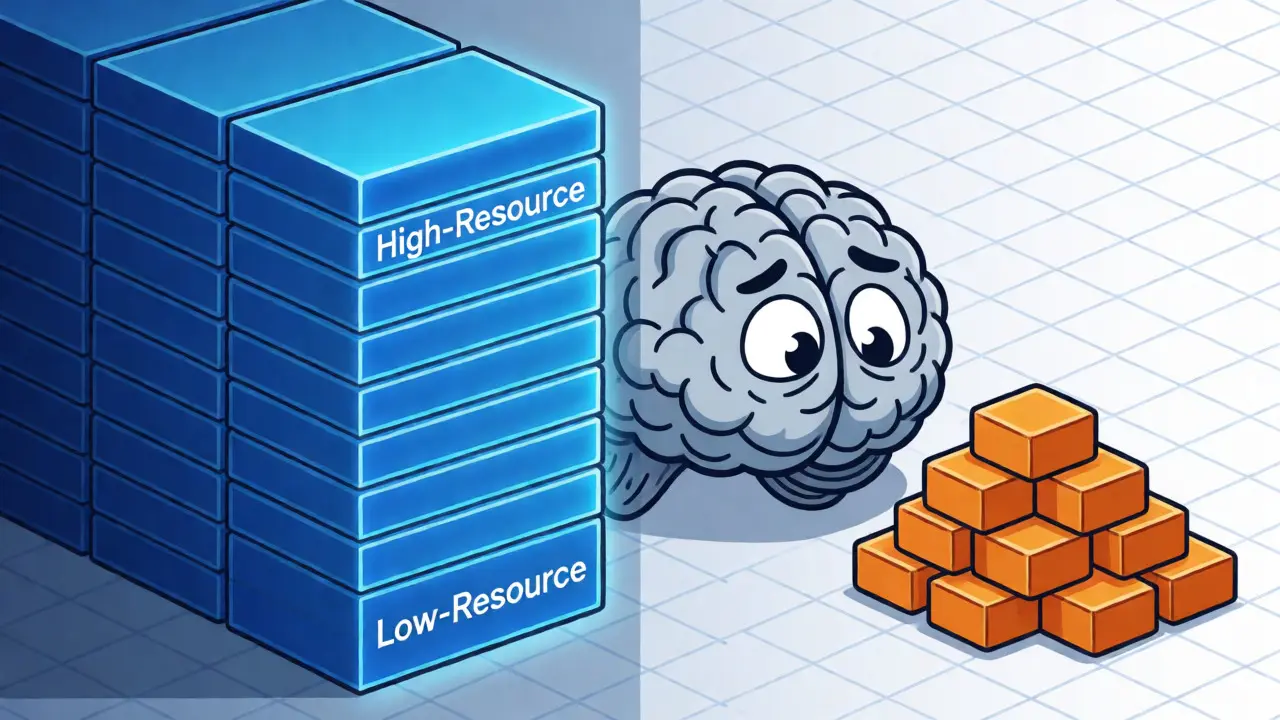
Imagine training a massive AI model that speaks English perfectly but stumbles over Swahili or Guarani. It’s not just an annoyance; it’s a billion-dollar problem. For years, we threw more data at the wall, hoping some of it would stick for every language. But here’s the twist: throwing more data doesn’t fix imbalance. In fact, naive approaches often make things worse for smaller languages. If you’re building multilingual systems today, understanding data balance isn’t optional-it’s the difference between a global product and a niche tool.
The core challenge lies in how we allocate training tokens. Most early models used proportional sampling, giving languages tokens based on their available data volume. This sounds fair until you realize English has billions of tokens while many African or Indigenous languages have millions. The result? A performance gap of 35-50% between high-resource and low-resource languages. Recent research, particularly the work by Tian et al. (2024), suggests a better way: deriving optimal sampling ratios from small-scale experiments. By training tiny models (85M parameters) and analyzing their loss curves, researchers can predict the perfect data mix for models 10x larger. This approach cuts trial-and-error by over 60%, saving both time and compute.
Why Proportional Sampling Fails Low-Resource Languages
Let’s look at the numbers. When you sample languages proportionally to their dataset size, high-resource languages like English dominate the gradient updates. The model learns English patterns deeply but barely scratches the surface for languages with limited data. Studies show that without intervention, cross-entropy loss for low-resource languages remains stubbornly high. Cross-lingual transfer helps-about 30-45% of gains come from learning related structures-but direct training data still matters. If a language has fewer than 50 million tokens, you hit a 'resource threshold effect.' No amount of clever sampling fixes a lack of fundamental exposure. You need enough raw data to establish basic grammar and vocabulary before optimization kicks in.
Consider the difference between mT5 and modern optimized models. mT5 used proportional sampling, leading to significant disparities. Modern frameworks like Meta’s NLLB introduced temperature-based sampling (alpha=0.3-0.7), which boosts low-resource performance by 18-25%. However, this comes at a cost: overall model efficiency drops by 12-15%. You’re trading general capability for specific coverage. Is that worth it? It depends on your use case. For a customer service bot serving diverse regions, yes. For a general-purpose chatbot, maybe not.
The Power-Law Approach to Data Allocation
Here is where it gets technical but practical. Researchers discovered a power-law relationship linking test loss to model size, dataset size, and sampling ratios. Think of it as a formula for fairness. By training over 100 models across 23 languages and 5 families, they mapped out exactly how much data each language needs to reach parity. For instance, a language with 1 billion tokens might only need 0.7% of total training tokens if balanced correctly, whereas English might need just 0.3% despite having 100x more data. This counter-intuitive insight changes everything. You don’t need equal data; you need equal *impact* per token.
This method isn’t magic. It relies on the assumption that language families behave somewhat independently in loss calculations. Dr. Anna Rogers from the University of Copenhagen warns that this might overlook cross-family influences. Structurally similar languages might share benefits, meaning you could undersample one and oversample another with little penalty. But for now, the math holds up remarkably well. Implementing these derived ratios allows low-resource languages to achieve 92-95% of high-resource performance levels, all while maintaining 98% of the model’s overall efficiency.
Comparing Balancing Strategies
Not all balancing acts are created equal. Below is a breakdown of common strategies and their trade-offs. This table highlights why "smarter" allocation beats "more" data.
| Strategy | Low-Resource Gain | Efficiency Cost | Best Use Case |
|---|---|---|---|
| Proportional Sampling | Baseline (High Gap) | None | English-dominant apps |
| Temperature-Based (NLLB) | +18-25% | -12-15% Efficiency | Broad coverage needs |
| Optimal Scaling Laws | +15-22% Loss Reduction | Maintains 98% Efficiency | Global enterprise deployment |
| Language-Adaptive Layers | +22-30% | +15-20% Latency | Real-time translation |
Notice the sweet spot with Optimal Scaling Laws. It offers significant gains without the heavy efficiency penalties of adaptive layers or the broad inefficiencies of temperature sampling. This is why companies like Meta are shifting toward scientifically derived ratios. Their recent Llama-Multilingual variants achieved 87-92% accuracy on XTREME benchmarks using 40% less compute than proportionally sampled models. That’s a massive win for budget-conscious teams.
Practical Implementation Pitfalls
You might be thinking, "Great, I’ll just plug in these ratios." Not so fast. Real-world implementation has hurdles. First, tokenization varies wildly. Turkish, being morphologically complex, requires 25-30% more raw tokens than English to cover the same vocabulary. If you ignore this, your effective dataset size is wrong, and your sampling ratios will be off. Second, code-switching is rampant. In many regions, 15-20% of communication mixes languages. Current scaling laws don’t fully account for this, potentially underestimating the data needed for mixed-language contexts.
Another trap is the "effective dataset size" estimation. Tools like LIUM help identify languages, but estimating true linguistic diversity within a corpus is hard. Developers on Hugging Face forums reported that for extremely low-resource languages like Guarani (<1M tokens), scaling law predictions overestimated performance by 35-40%. Manual adjustment was necessary. Don’t trust the math blindly for outliers. Validate with small-scale tests first. An 85M parameter model run on 2-3 A100 GPUs for 3-5 days gives you reliable data points without breaking the bank.
Future Trends and Regulatory Pressures
The landscape is shifting from "more data" to "better data." IDC reports the multilingual AI market hit $4.8 billion in Q3 2024, growing at 34.7% year-over-year. Enterprises are waking up to the fact that balanced models reduce failure rates. AWS users saw language-specific failures drop from 22% to 8% after optimizing sampling. This isn’t just about quality; it’s about compliance. The EU’s AI Act, effective February 2025, demands demonstrable fairness across supported languages. If your model favors English, you might face regulatory scrutiny.
Looking ahead, dynamic sampling is emerging. Google Research plans to adjust ratios in real-time based on performance monitoring, promising another 8-12% gain for struggling languages. Meanwhile, multimodal models like PaLI-X show that scaling vision and language together improves captioning accuracy by 22.4%. The future isn’t just text; it’s context-aware, visually grounded, and linguistically equitable. Organizations implementing these strategies report 28% faster time-to-market and savings of $1.2-1.8 million per iteration. The question isn’t whether to balance your data, but how quickly you can implement it before competitors do.
What is the resource threshold effect in multilingual LLMs?
The resource threshold effect occurs when a language has fewer than 50 million training tokens. At this level, adjusting sampling ratios yields diminishing returns because the model lacks sufficient exposure to learn basic grammar and vocabulary, regardless of how frequently those tokens appear during training.
How does optimal sampling compare to temperature-based sampling?
Temperature-based sampling (used in NLLB) improves low-resource performance by 18-25% but reduces overall model efficiency by 12-15%. Optimal sampling, derived from scaling laws, achieves similar or better gains (15-22% loss reduction) while maintaining 98% of the model's efficiency, making it more sustainable for large-scale deployments.
Can scaling laws derived from 23 languages apply to all 7,000+ languages?
Probably not directly. Experts like Professor Graham Neubig caution that laws derived from major language families may not generalize to languages with radically different morphological structures. For rare or structurally unique languages, manual adjustment and small-scale validation are still required.
Why is tokenization important for data balance?
Tokenization efficiency varies by language. Morphologically complex languages like Turkish require 25-30% more raw tokens than English to represent equivalent information. Ignoring this leads to inaccurate estimates of "effective dataset size," causing suboptimal sampling ratios and uneven performance.
How does code-switching affect multilingual model training?
Code-switching affects 15-20% of natural communication in multilingual regions. Current scaling laws often treat languages as independent, overlooking these mixed-language patterns. This can lead to underestimating the data needed for robust performance in regions where speakers frequently switch between languages mid-sentence.
Jacob Baby Official
September 6, 2026 AT 06:40This is absolute garbage. You're ignoring the fact that 'optimal' scaling laws are just curve-fitting exercises for people who don't understand linguistics.
Everyone knows that language isn't a math problem, it's a cultural artifact. By trying to balance tokens, you destroy the nuance of high-resource languages to prop up low-resource ones that nobody actually uses in enterprise contexts. It's performative equity at best and computational waste at worst. The 35-50% gap exists because English has more utility, not because we didn't sample enough Swahili. Stop pretending that a tiny model can predict the behavior of a billion-parameter beast without massive error bars.
john randall
September 8, 2026 AT 02:35Yeah, I see where he's coming from with the skepticism, but the data on NLLB and Llama-Multilingual seems pretty solid if you look past the theoretical arguments. It’s less about replacing linguistic understanding and more about efficient resource allocation when compute is limited.
Chris Neal
September 9, 2026 AT 00:05Actually, the power-law approach works precisely because it accounts for diminishing returns per token. If you read Tian et al. properly, they aren't claiming perfect prediction, they are claiming a significant reduction in search space. The efficiency gain of maintaining 98% overall performance while boosting low-resource accuracy by 20%+ is too big to ignore. Ignoring this because it feels 'too mathematical' misses the point of engineering optimization.
Jeff Falcon
September 9, 2026 AT 02:16I mean, honestly, I think everyone is missing the bigger picture here?? Like, sure, the sampling ratios are cool, and the loss curves are interesting, BUT... what about the actual human element??? We’re treating languages like they’re just bags of words, or something, and that’s so reductive!!!
When you force these optimal ratios, you might get better benchmark scores, yeah, but does the model actually *feel* the language? Does it understand the poetry, the slang, the vibe? I feel like we’re optimizing for metrics that don’t matter as much as connection, you know??? And also, the table is nice, but it doesn’t tell me how to talk to my grandmother in Guarani without sounding like a robot!!!
Joanna Mucha
September 10, 2026 AT 07:47The obsession with quantitative parity is a symptom of our collective inability to sit with ambiguity. To reduce the soul of a language to a 'sampling ratio' is an act of profound violence against the spirit of communication. These models do not speak; they merely mimic the statistical shadows of speech. True understanding requires presence, not probability distributions.
Alyson Karson
September 10, 2026 AT 20:42LOL okay but can we talk about the tokenization issue?? That Turkish example is HUGE. If your tokenizer eats up 30% more tokens for agglutinative languages, your 'balanced' dataset is actually skewed AGAIN before you even start training!! This article glosses over it too fast. Fix your tokenizers first or your fancy math is useless!!!
Brenna Gonedrman
September 11, 2026 AT 15:40It’s not just Turkish! Every morphologically rich language suffers. If you don’t adjust for subword unit length, you are effectively under-training those languages regardless of your sampling strategy. This is basic preprocessing stuff that gets ignored because it’s tedious.
tiffany King
September 13, 2026 AT 00:08This is such exciting news for developers working on global apps! Finally, a way to make our products inclusive without breaking the bank on compute costs. The shift towards scientifically derived ratios gives me so much hope for better support for smaller languages!
Kim Edwards
September 13, 2026 AT 20:53Wait, hold on. Did anyone else catch the part about code-switching being rampant? 15-20%?! That means nearly one in five interactions is mixed language. If our scaling laws don't account for that, we are building systems that fail exactly where users need them most-in the messy, beautiful chaos of real life. This isn't just a technical glitch; it's a fundamental design flaw in how we view multilingualism. We need adaptive layers NOW.
Courtney Wagstaff
September 13, 2026 AT 21:29Love the breakdown of the strategies! The temperature-based sampling vs. optimal scaling comparison was super helpful for my current project. Definitely going to try implementing the derived ratios instead of just throwing more data at the wall. Thanks for sharing this!