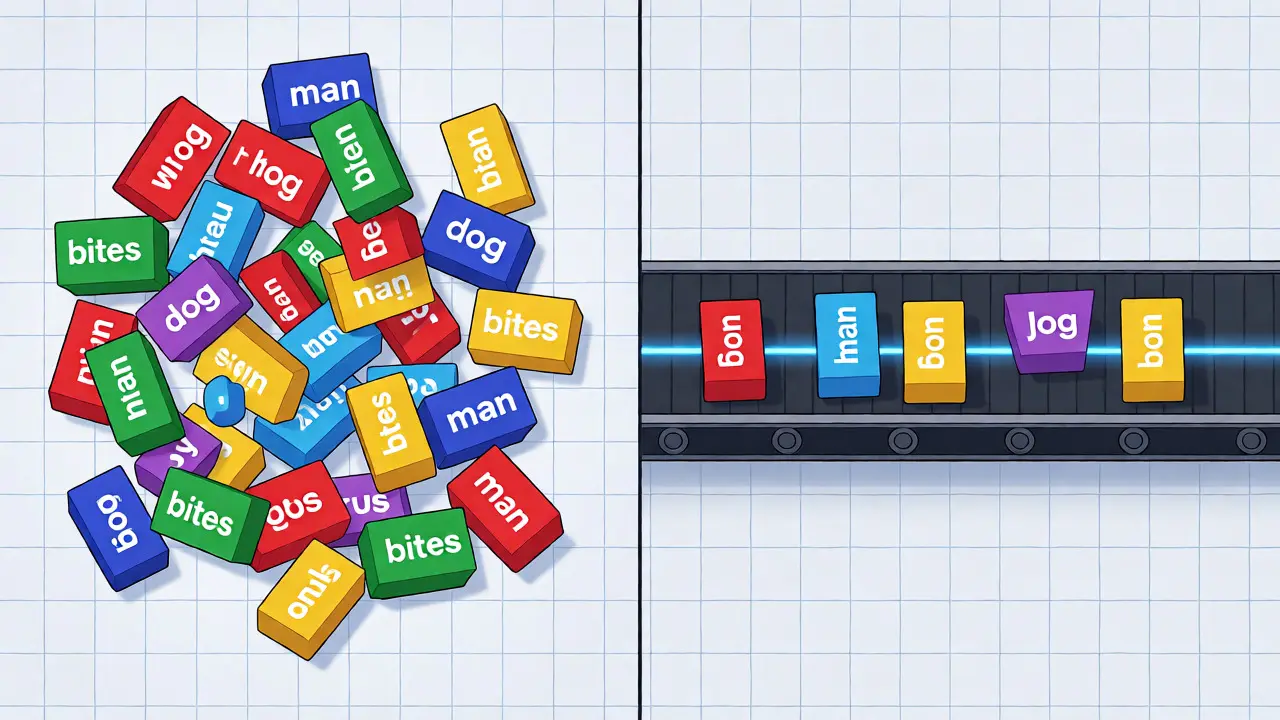
Have you ever wondered how a computer knows that "dog bites man" is different from "man bites dog"? To a raw neural network processing tokens independently, both sentences look like the same unordered bag of words. The magic that fixes this lies in positional encoding. It is a technique that injects sequence order into data so that transformer models can understand context and syntax.
If you are building or fine-tuning large language models (LLMs), understanding positional encoding isn't just academic trivia-it's critical for performance. Get it wrong, and your model might hallucinate word orders or fail to generalize to longer texts. This guide breaks down why transformers need position awareness, how the original sine-cosine method works, and what strategies modern generative AI uses today.
Why Transformers Need Position Awareness
The core innovation of the Transformer architecture, introduced by Vaswani et al. in 2017, was replacing recurrent layers with self-attention. Self-attention allows the model to weigh the importance of every token in a sequence against every other token simultaneously. This makes training parallelizable and incredibly fast compared to older RNNs or LSTMs.
But there is a catch: self-attention is permutation-invariant. If you shuffle the input tokens, the attention scores between them remain identical because the mechanism only looks at content similarity, not location. Without extra help, the model cannot distinguish between "The cat sat on the mat" and "Mat the on sat cat." Positional information must be explicitly added to the token embeddings to break this symmetry.
The Original Solution: Sinusoidal Positional Encodings
Vaswani et al. proposed a fixed, non-trainable approach using sine and cosine functions. Instead of learning where each word sits, they calculated a unique fingerprint for every position based on mathematical waves. Why waves? Because they allow the model to easily learn relative positions.
Here is the formula for a given position pos and dimension index i within a model dimension d_model:
- Even dimensions:
PE(pos, 2i) = sin(pos / 10000^(2i/d_model)) - Odd dimensions:
PE(pos, 2i+1) = cos(pos / 10000^(2i/d_model))
This structure creates a geometric progression of frequencies. Lower dimensions oscillate slowly, capturing broad positional context, while higher dimensions oscillate rapidly, capturing fine-grained differences between adjacent tokens. This multi-scale approach means the model can track both local syntax and long-range dependencies.
| Strategy | Type | Generalization | Relative Position Support | Memory Cost |
|---|---|---|---|---|
| Sinusoidal | Fixed | Excellent (extrapolates) | Inherent via linear transformation | Low (computed on fly) |
| Learned Embeddings | Trainable | Limited to max length seen | Implicitly learned | High (stored matrix) |
| RoPE | Rotary | Good with scaling | Direct integration | Medium |
How Sinusoidal Encodings Enable Relative Attention
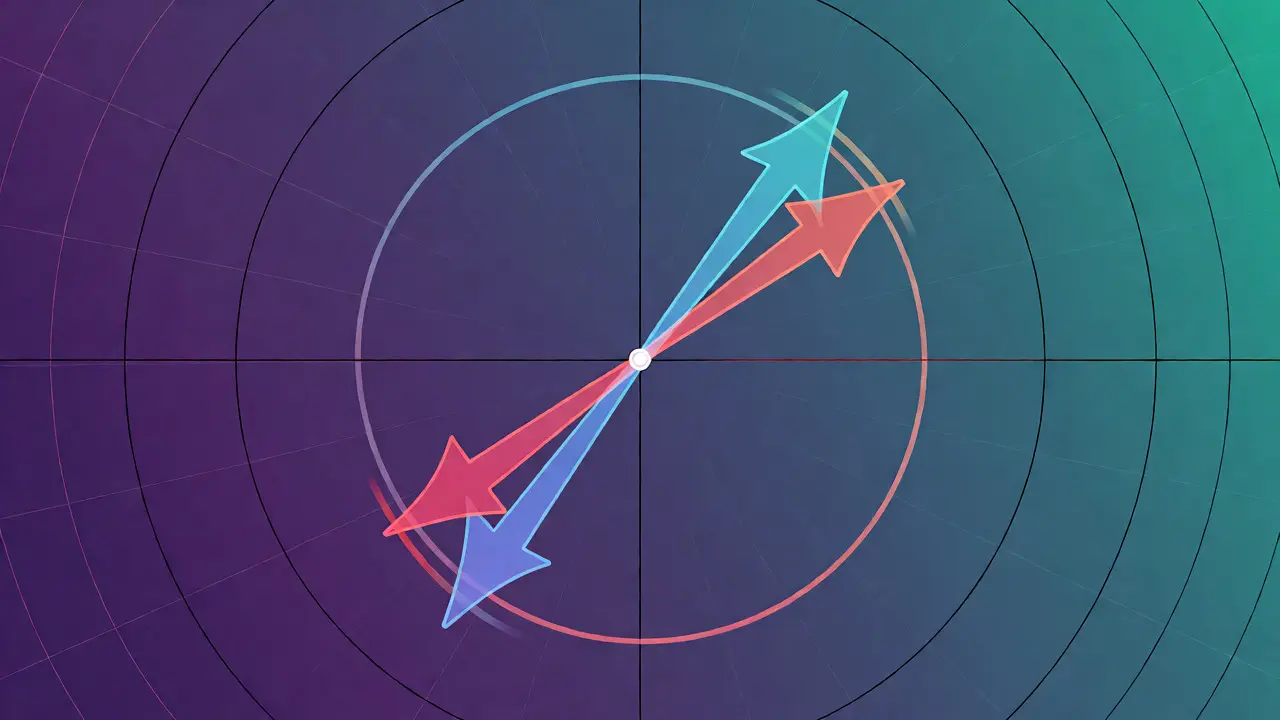
The genius of the sine-cosine choice isn't just uniqueness; it's about relationships. For any fixed offset k, the positional encoding at pos + k can be represented as a linear function of the encoding at pos. Mathematically, this resembles a rotation matrix.
When the transformer calculates attention scores, it effectively compares these rotated vectors. This allows the model to attend to relative distances without needing to know absolute indices. In simpler terms, if the model learns that "the" usually precedes "cat," it doesn't matter if that pair appears at position 5 or position 500. The relative signal remains consistent. This property is crucial for handling variable-length sequences during inference.
Learned vs. Fixed: The Trade-Offs
While sinusoidal encodings are elegant, many modern implementations switched to learnable positional embeddings. Here, the model treats position as another vocabulary entry. You create an embedding matrix of size max_seq_length × d_model and train it alongside the rest of the network.
Why switch? Learned embeddings offer flexibility. The model can discover complex positional patterns that simple waves might miss. However, they come with significant downsides. First, they require storing a massive matrix in memory. Second, they struggle with extrapolation. If you train on sequences up to 512 tokens, the model has no learned representation for position 513. When you try to generate text longer than the training limit, performance often degrades sharply.
Fixed sinusoidal encodings don't have this problem. Since they are computed mathematically, you can calculate the encoding for position 10,000 even if you only trained up to 512. This makes them robust for tasks requiring long-context generation, though they may lack the nuanced adaptability of learned embeddings for specific domain quirks.
Modern Evolutions: Rotary and Beyond
As generative AI scales, new strategies have emerged to address the limitations of both fixed and learned approaches. One prominent example is Rotary Positional Embedding (RoPE), used in models like LLaMA and PaLM.
Instead of adding positional information to the embeddings before attention, RoPE rotates the query and key vectors directly within the attention mechanism. This integrates positional information multiplicatively rather than additively. The result is a more direct encoding of relative positions. RoPE tends to perform better on long-context benchmarks and supports easier extension techniques like YaRN (Yet another RoPE extensioN), which allows models to handle significantly longer sequences than originally trained on.
Another trend is decoupled attention, where some layers focus on local windows while others handle global context. This reduces the computational burden of attending to every token across vast distances, making real-time generation feasible for ultra-long documents.
Implementation Pitfalls and Best Practices
If you are implementing these strategies yourself, watch out for common traps. A frequent error is mismatching the dimensionality. Ensure that the positional encoding vector matches the hidden state size (d_model) exactly. Mismatches cause broadcasting errors or silent degradation in accuracy.
Also, consider normalization. Some architectures apply layer normalization after adding positional encodings. Others do it before. The order matters because positional signals can dominate semantic signals if not balanced correctly. Always validate your implementation by checking if the model can reconstruct shuffled sentences-a quick sanity check for position awareness.
For developers working with PyTorch or TensorFlow, remember that computing sinusoidal encodings on the fly saves memory but costs CPU cycles. Pre-computing them for known max lengths speeds up training but increases RAM usage. Choose based on your hardware constraints and sequence length variability.
Frequently Asked Questions
Can I use zero positional encoding?
Technically, yes, but it removes all order information. The model would treat inputs as sets, not sequences. This works for tasks like document classification where order matters less, but fails for language generation or translation.
Why is the base value 10000 used in sinusoidal encodings?
Vaswani et al. chose 10000 empirically. It provides a wide range of wavelengths, ensuring that high-frequency components capture local details while low-frequency components cover global context. Changing this base alters the frequency spectrum and may impact performance on specific datasets.
Do all transformers use the same positional strategy?
No. GPT models initially used learned embeddings, while BERT variants often used sinusoidal or learned hybrids. Modern open-source models like LLaMA prefer RoPE for its superior long-context handling. The choice depends on the specific architectural goals and training data characteristics.
How does positional encoding affect inference speed?
Fixed encodings have negligible inference cost since they are pre-calculated or cheap to compute. Learned embeddings require lookup operations, which are also fast but consume memory. Complex mechanisms like RoPE involve trigonometric calculations during attention, adding slight overhead but improving quality.
What happens if my input exceeds the maximum positional embedding length?
With learned embeddings, you typically truncate the input or get undefined behavior for unseen positions. With sinusoidal or RoPE, you can compute encodings for arbitrary positions, allowing the model to process longer sequences, though performance may degrade if the model hasn't seen such lengths during training.