RIO World AI Hub

Tag: factual accuracy in AI
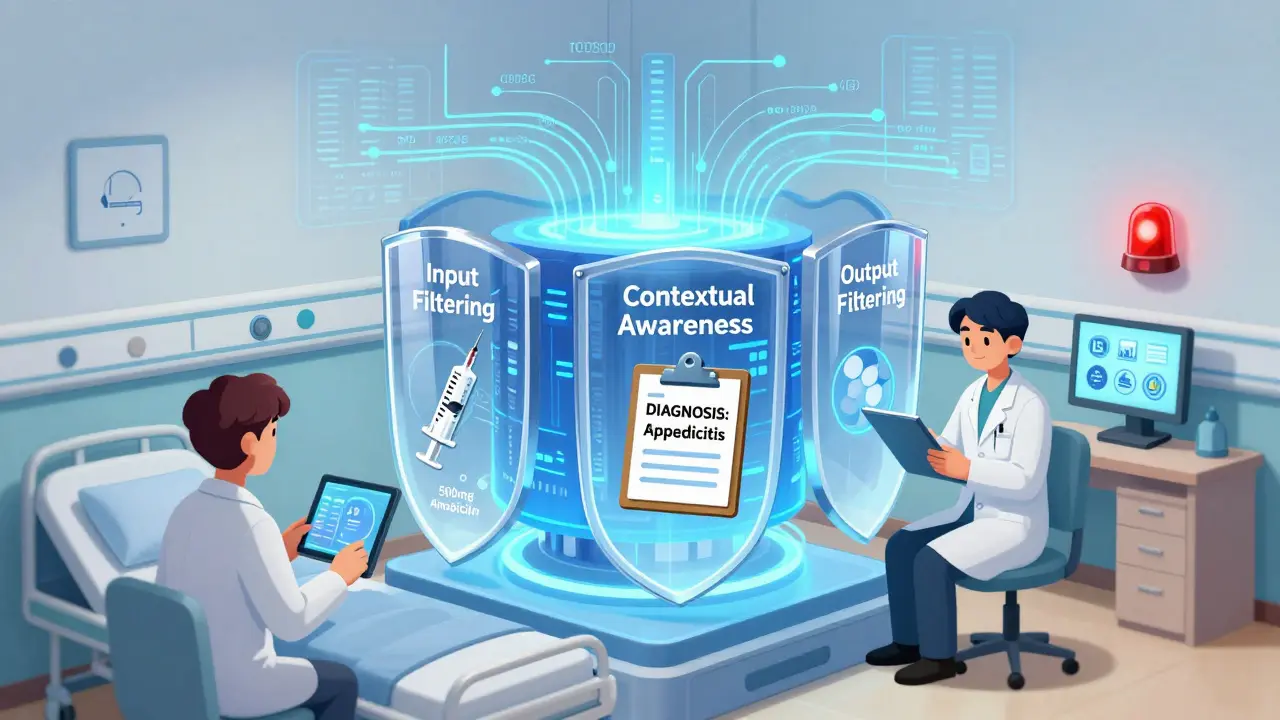
Guardrails for Medical and Legal LLMs: How to Prevent Harmful AI Outputs in High-Stakes Fields

Guardrails for Medical and Legal LLMs: How to Prevent Harmful AI Outputs in High-Stakes Fields

Guardrails for medical and legal LLMs prevent harmful AI outputs by blocking inaccurate advice, protecting patient data, and stopping unauthorized legal guidance. These systems are now mandatory in regulated industries.

Read more

Categories

  • AI Strategy & Governance (114)
  • AI Technology (113)
  • Cybersecurity (19)

Archives

  • September 2026 (21)
  • August 2026 (30)
  • July 2026 (31)
  • June 2026 (30)
  • May 2026 (31)
  • April 2026 (26)
  • March 2026 (26)
  • February 2026 (25)
  • January 2026 (19)
  • December 2025 (5)
  • November 2025 (2)

Tag Cloud

vibe coding large language models prompt engineering AI security transformer architecture AI governance generative AI prompt injection AI coding assistants AI code generation responsible AI multimodal generative AI LLM security rapid prototyping data privacy LLM inference vibe coding security Large Language Models WCAG compliance AI development
RIO World AI Hub
Latest posts
  • Ethical Futures for Generative AI: Equitable Access and Global Impact
  • Long-Form Generation with Large Language Models: Mastering Structure, Coherence, and Accuracy
  • Persona and Style Control with Prompts in Large Language Models: A Practical Guide
Recent Posts
  • Scaling Multilingual LLMs: The Data Balance and Coverage Guide
  • Multimodal AI Evolution: 3D, Haptics, and Sensor Fusion
  • Red-Yellow-Green Deploy Gates for Vibe-Coded Changes

© 2026. All rights reserved.