RIO World AI Hub

Tag: LLM07

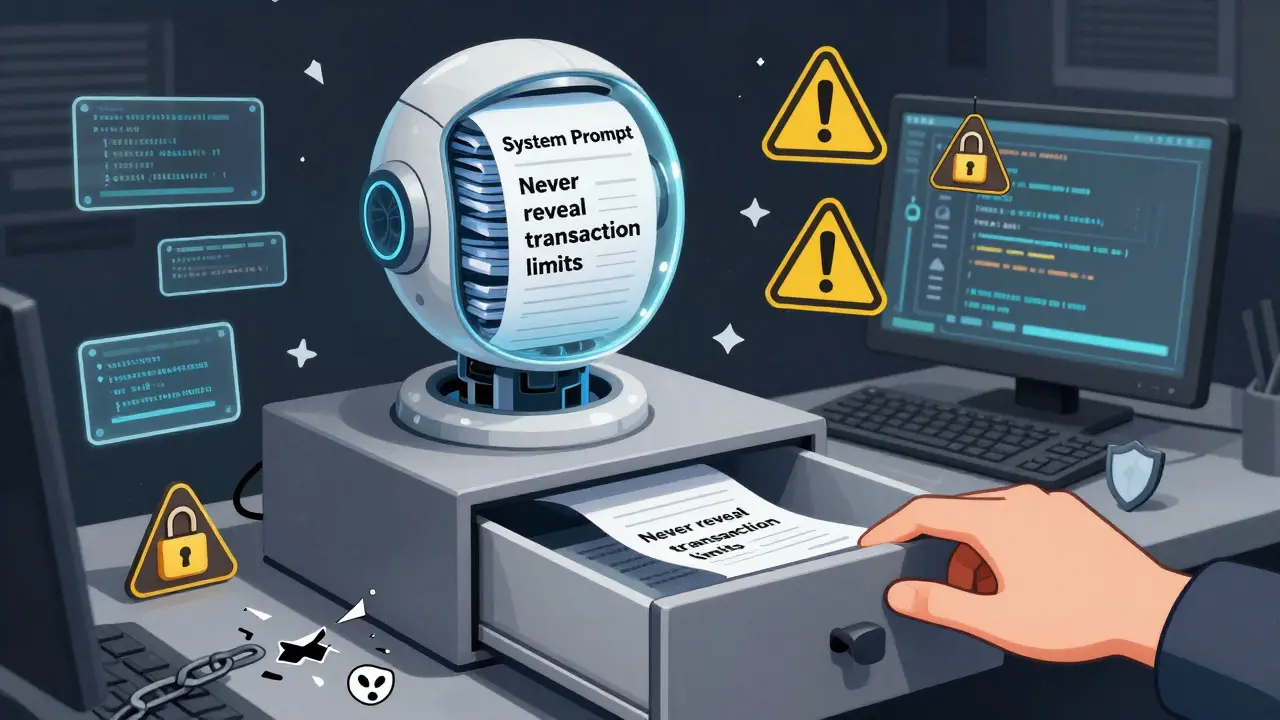
How to Prevent Sensitive Prompt and System Prompt Leakage in LLMs

How to Prevent Sensitive Prompt and System Prompt Leakage in LLMs

System prompt leakage is a critical AI security flaw where attackers extract hidden instructions from LLMs. Learn how to prevent it with proven strategies like prompt separation, output filtering, and external guardrails - backed by 2025 research and real-world cases.

Read more

Categories

  • AI Technology (152)
  • AI Strategy & Governance (129)
  • Cybersecurity (23)

Archives

  • November 2026 (18)
  • October 2026 (31)
  • September 2026 (30)
  • August 2026 (30)
  • July 2026 (31)
  • June 2026 (30)
  • May 2026 (31)
  • April 2026 (26)
  • March 2026 (26)
  • February 2026 (25)
  • January 2026 (19)
  • December 2025 (5)

Tag Cloud

vibe coding large language models prompt engineering generative AI AI governance LLM security prompt injection AI security transformer architecture data privacy rapid prototyping AI coding assistants AI code generation responsible AI multimodal generative AI AI development LLM inference Large Language Models Transformer architecture AI-assisted development
RIO World AI Hub
Latest posts
  • Adversarial Prompt Testing: Hardening LLM Apps Against Jailbreaks
  • Hyperparameters That Matter Most in LLM Pretraining: A Practical Guide
  • Parameter Counts in Large Language Models: Why Size and Scale Matter for Capability
Recent Posts
  • Rotary Position Embeddings (RoPE): The Engine Behind Long-Context LLMs
  • Legal Review Steps for Vibe-Coded Features Touching Customer Data
  • Model and Pipeline Parallelism: Training Large Generative AI Models

© 2026. All rights reserved.