Tag: AI safety
Adversarial Examples for LLMs: How Jailbreaks and Overrides Work
Discover how adversarial examples, jailbreaks, and overrides compromise Large Language Models. Learn about text suffixes, visual attacks, and practical defense strategies to secure your AI applications against evolving security risks.
Read more
Human-in-the-Loop Practices for Safe and Effective Vibe Coding
Discover how human-in-the-loop practices make vibe coding safe and effective. Learn practical steps to integrate oversight into AI-assisted development.
Read more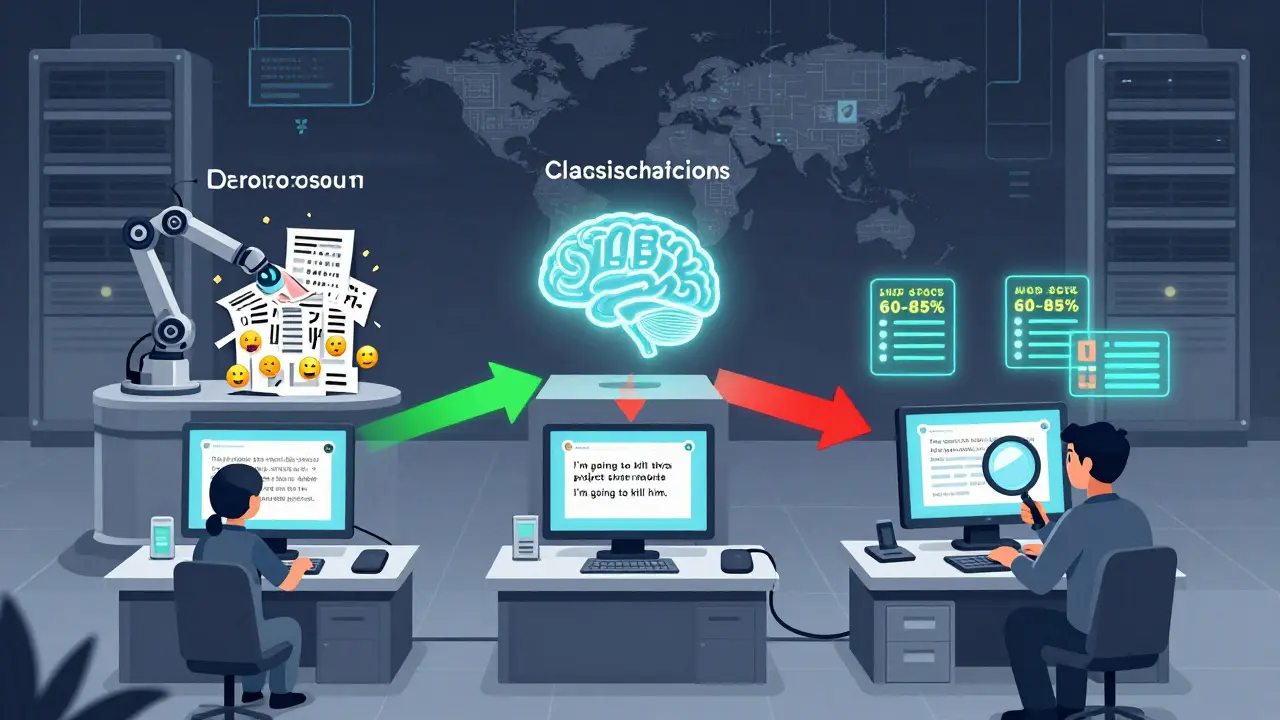
Content Moderation Pipelines for User-Generated Inputs to LLMs: How to Block Harmful Content Without Breaking Trust
Learn how modern AI systems filter harmful user inputs before they reach LLMs using layered pipelines, policy-as-prompt techniques, and hybrid NLP+LLM strategies that balance safety, cost, and fairness.
Read more