RIO World AI Hub

Tag: MMLU-Pro

Evaluation Benchmarks for Generative AI: MMLU, Image Fidelity & Beyond

Evaluation Benchmarks for Generative AI: MMLU, Image Fidelity & Beyond

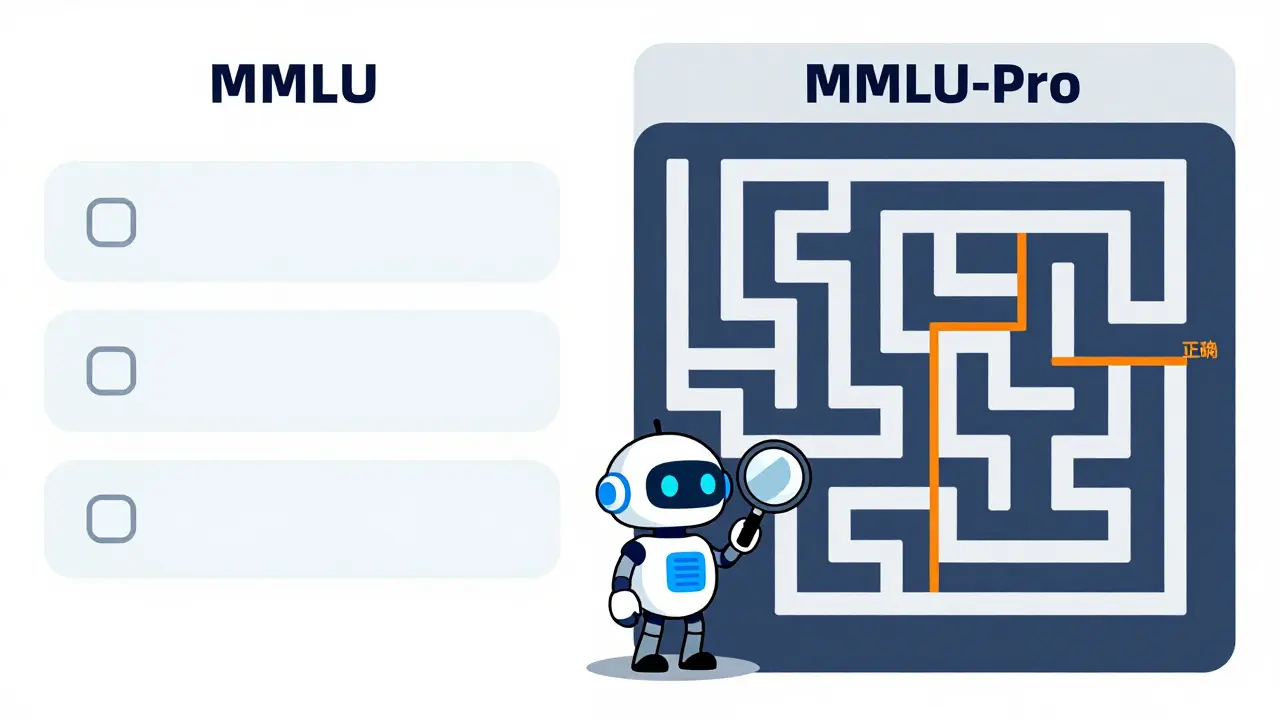
Explore how AI evaluation benchmarks have evolved from MMLU to MMLU-Pro and image fidelity metrics. Learn why reasoning depth and contamination-free testing matter for choosing the right generative AI model.

Read more

Categories

  • AI Technology (131)
  • AI Strategy & Governance (120)
  • Cybersecurity (22)

Archives

  • October 2026 (18)
  • September 2026 (30)
  • August 2026 (30)
  • July 2026 (31)
  • June 2026 (30)
  • May 2026 (31)
  • April 2026 (26)
  • March 2026 (26)
  • February 2026 (25)
  • January 2026 (19)
  • December 2025 (5)
  • November 2025 (2)

Tag Cloud

vibe coding large language models prompt engineering generative AI AI governance AI security transformer architecture data privacy LLM security prompt injection rapid prototyping AI coding assistants AI code generation responsible AI multimodal generative AI LLM inference AI development vibe coding security LLM hallucinations LoRA
RIO World AI Hub
Latest posts
  • Sparse and Dynamic Routing in LLMs: The MoE Revolution Explained
  • Copyright and Generative AI: Navigating Fair Use, Licensing, and Data Provenance
  • Vibe Coding Myths and Facts: Separating Hype from Reality
Recent Posts
  • Retraining After Compression: How to Restore LLM Accuracy Without Full Fine-Tuning
  • Localization and Accessibility in Vibe-Coded Interfaces: A Practical Guide
  • Sales and Generative AI: Battlecards, Call Summaries, and Objection Handling

© 2026. All rights reserved.