Tag: LLM compression
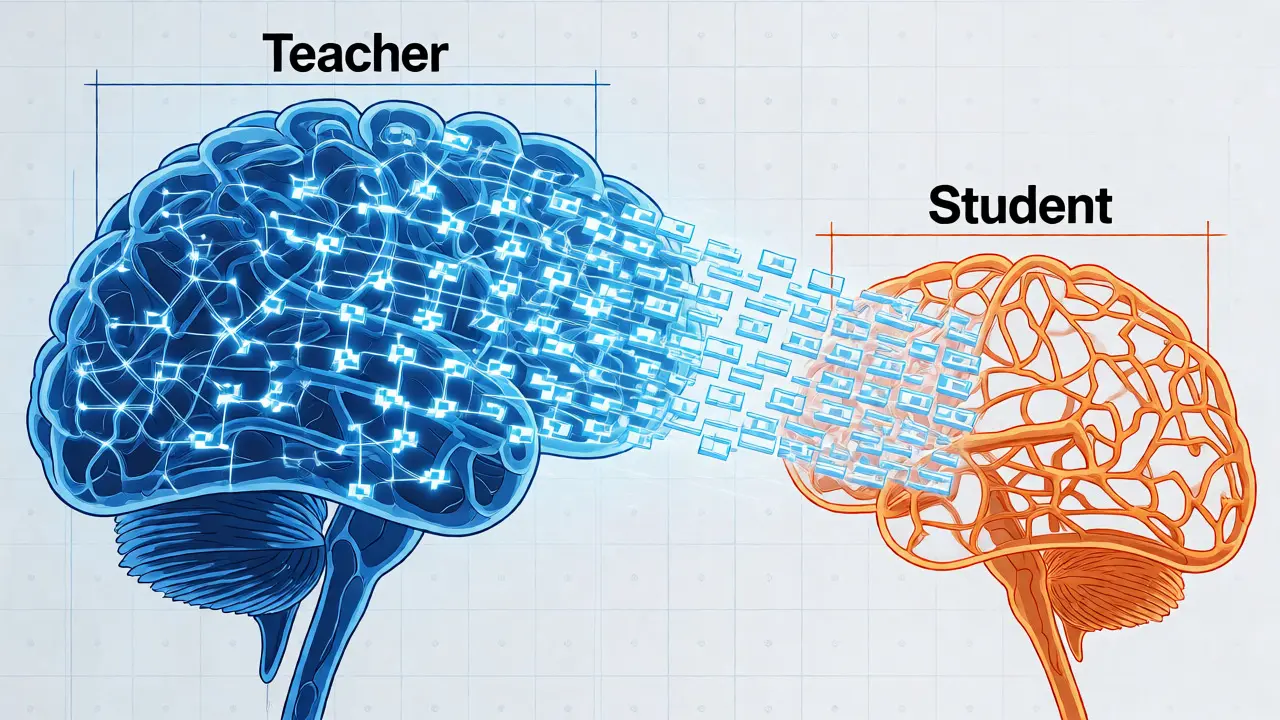
Distilling Reasoning: How Small LLMs Learn Chain-of-Thought
Discover how smaller language models learn to reason via Chain-of-Thought distillation. We compare pre-thinking vs. post-thinking methods, analyze performance gaps, and offer practical tips for implementation.
Read more
Retraining After Compression: How to Restore LLM Accuracy Without Full Fine-Tuning
Learn how to restore accuracy in compressed LLMs without expensive full retraining. Discover methods like local reconstruction, EoRA, and prompt-based recovery.
Read more
Compression Impact on Multilingual and Domain-Specific Large Language Models
Explore how LLM compression impacts multilingual accuracy and domain-specific reliability. Learn why low-resource languages suffer, the risks in medical/legal AI, and how to avoid the perplexity trap.
Read more