RIO World AI Hub

Tag: LLM privacy

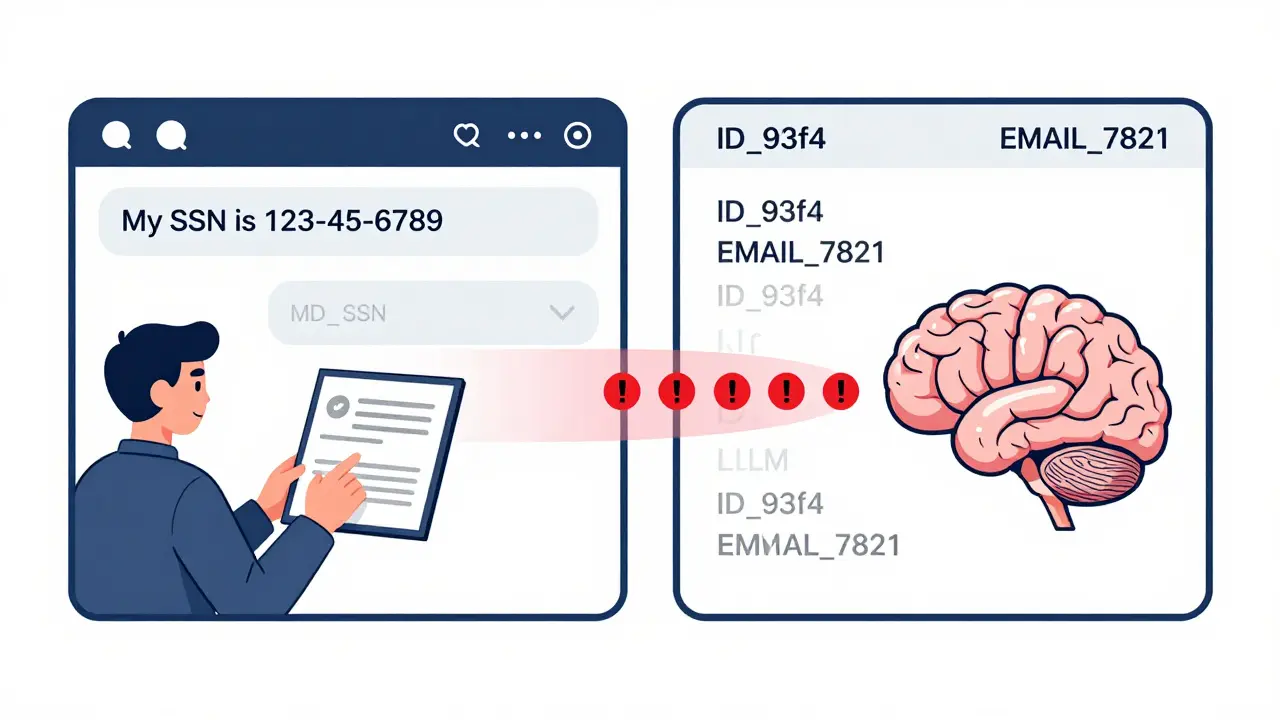
Token-Level Logging Minimization: How to Protect Privacy in LLM Systems Without Killing Performance

Token-Level Logging Minimization: How to Protect Privacy in LLM Systems Without Killing Performance

Token-level logging minimization stops sensitive data from being stored in LLM logs by replacing PII with anonymous tokens. Learn how it works, why it's required by GDPR and the EU AI Act, and how to implement it without killing performance.

Read more

Categories

  • AI Strategy & Governance (112)
  • AI Technology (110)
  • Cybersecurity (18)

Archives

  • September 2026 (15)
  • August 2026 (30)
  • July 2026 (31)
  • June 2026 (30)
  • May 2026 (31)
  • April 2026 (26)
  • March 2026 (26)
  • February 2026 (25)
  • January 2026 (19)
  • December 2025 (5)
  • November 2025 (2)

Tag Cloud

vibe coding large language models prompt engineering AI security transformer architecture generative AI AI governance AI coding assistants AI code generation responsible AI multimodal generative AI LLM security prompt injection rapid prototyping data privacy LLM inference vibe coding security Large Language Models WCAG compliance AI development
RIO World AI Hub
Latest posts
  • Tool Use with Large Language Models: Function Calling and External APIs
  • Hardware Trends That Accelerate Vibe Coding: GPUs, NPUs, and Edge
  • How to Prove Generative AI ROI: Solving the Attribution Problem in 2026
Recent Posts
  • Quantization-Friendly Transformers for Edge LLMs: A Practical Guide
  • LLM Output Calibration Across Languages: Fixing Non-English Accuracy
  • Latency vs Throughput Tradeoffs in Production LLM Deployments

© 2026. All rights reserved.