Tag: self-attention mechanism
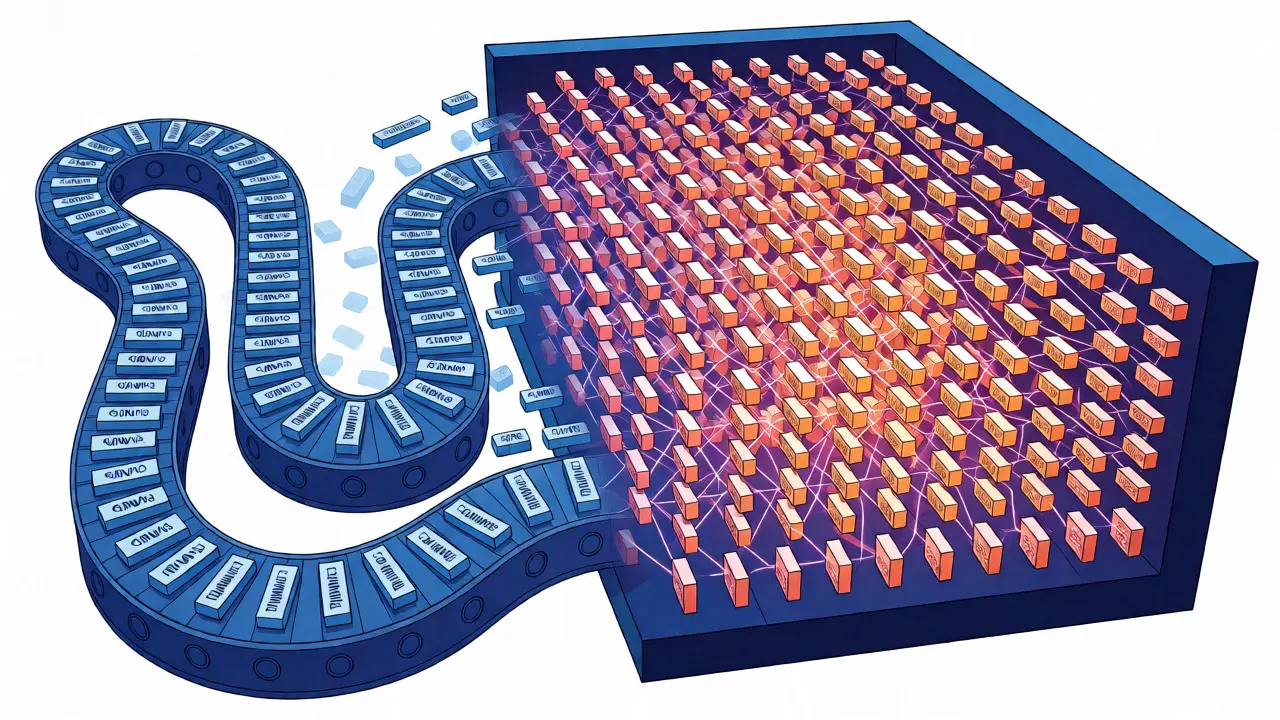
Self-Attention and Positional Encoding: The Engine Behind Generative AI
Discover how self-attention and positional encoding power the Transformer architecture behind modern Generative AI. Learn why parallel processing requires injected order, common implementation pitfalls, and how these mechanisms enable coherent text generation.
Read more
How Large Language Models Work: Core Mechanisms and Capabilities
Explore the inner workings of Large Language Models, from Transformer architecture and self-attention to tokenization and the battle against hallucinations.
Read more